Evaluating Performance in Parallel Computing
Evaluating a parallel program means more than asking whether it runs faster with more processors. Good performance analysis looks at how much faster it becomes, how efficiently it uses additional resources, where time is lost, and whether the behavior remains stable as the workload or machine size grows.
The most useful measurements combine application-level metrics such as latency and throughput with parallel-specific metrics such as speedup, efficiency, load balance, communication cost, synchronization time, and scaling behavior.
Performance Metrics
I. Throughput
- Throughput is the amount of useful work completed per unit of time.
- Depending on the application, the unit may be requests/second, images/second, iterations/second, transactions/second, or processed bytes/second.
- Higher throughput is usually desirable, but it should be interpreted together with latency, correctness, and resource consumption.
- A system can improve throughput without improving the latency of an individual task.
A simple definition is:
$$ \text{Throughput} = \frac{\text{completed work}}{\text{elapsed time}} $$
For example, if a program processes 12,000 images in 60 seconds:
$$ \text{Throughput} = \frac{12000}{60} = 200 \text{ images/s} $$
II. Latency
- Latency is the elapsed time required for one operation, request, or unit of work to complete.
- Lower latency is especially important for interactive systems and applications with deadlines.
- In parallel systems, latency can include computation, communication, queueing, synchronization, and waiting for slower workers.
For one operation:
$$ \text{Latency} = t_{\text{finish}} - t_{\text{start}} $$
When many operations are measured, the average alone may hide slow outliers. Percentiles such as p50, p95, and p99 latency are often more informative for services and irregular workloads.
III. Speedup
- Speedup measures how much faster a parallel implementation is than a reference implementation.
- The usual reference is the execution time on one processor using the same algorithm and problem size.
- Speedup should be based on wall-clock elapsed time, because that is the time observed by the user.
$$ S_p = \frac{T_1}{T_p} $$
where:
- $T_1$ is the execution time using one processor.
- $T_p$ is the execution time using $p$ processors.
Example:
If a computation takes 100 seconds on one processor and 28 seconds on four processors:
$$ S_4 = \frac{100}{28} \approx 3.57 $$
The ideal speedup with four processors is $4$, so this result is good but not perfectly linear.
Speedup can occasionally be superlinear, where $S_p > p$. This does not mean the processors are violating the usual scaling limits. It can happen because the parallel run has a more favorable cache working set, reduces paging, or changes the algorithm's effective behavior.
IV. Efficiency
- Parallel efficiency measures how effectively the available processors contribute to speedup.
- It is speedup normalized by the number of processors.
$$ E_p = \frac{S_p}{p} $$
It is often expressed as a percentage:
$$ E_p(\%) = \frac{S_p}{p} \times 100 $$
Using the previous example:
$$ E_4 = \frac{3.57}{4} \approx 0.893 = 89.3\% $$
An efficiency near $1$ indicates that the additional processors are being used effectively. Efficiency usually decreases as the processor count grows because communication, synchronization, and serial work become more significant.
V. Scalability
- Scalability describes how performance changes as more processing resources are added.
- A scalable program continues to gain useful performance without communication, synchronization, memory contention, or serial work dominating the runtime.
- Scalability should be measured experimentally rather than inferred only from CPU utilization.
Two common scaling models are used.
Strong Scaling:
- The total problem size remains fixed while the number of processors increases.
- The goal is to complete the same work in less time.
- Strong-scaling speedup is usually measured with $S_p = T_1/T_p$.
- Strong scaling eventually saturates because the work per processor becomes too small relative to communication and synchronization overhead.
A useful strong-scaling efficiency is:
$$ E_{\text{strong}}(p) = \frac{T_1}{pT_p} $$
Weak Scaling:
- The problem size per processor remains approximately fixed while the processor count increases.
- The total amount of work therefore grows with the machine size.
- The goal is to accomplish more total work in roughly the same time.
If $T_1$ is the runtime for one unit of work on one processor and $T_p$ is the runtime for $p$ units of work on $p$ processors, one common weak-scaling efficiency is:
$$ E_{\text{weak}}(p) = \frac{T_1}{T_p} $$
A value near $1$ indicates that runtime stayed nearly constant while the total workload grew.
VI. Load Balancing
- Load balancing describes how evenly useful work is distributed across processors, threads, GPU blocks, or cluster nodes.
- Poor load balance causes some workers to wait while the slowest worker finishes.
- In synchronized parallel programs, overall runtime is often determined by the slowest participant.
If worker execution times are $T_1, T_2, \ldots, T_p$, a simple imbalance indicator is:
$$ \text{Imbalance} = \frac{T_{\max}}{T_{\text{avg}}} $$
where:
$$ T_{\text{avg}} = \frac{1}{p}\sum_{i=1}^{p} T_i $$
An imbalance close to $1$ is desirable. Larger values indicate that one or more workers are doing substantially more work than the others.
Common causes of imbalance include:
- Uneven input data.
- Tasks with unpredictable execution times.
- Static partitioning of irregular workloads.
- Different processor speeds or NUMA placement.
- Contention for shared resources.
- Stragglers in distributed systems.
Dynamic scheduling, work queues, work stealing, and finer-grained task decomposition can improve balance, although they introduce scheduling overhead.
VII. Overhead
- Parallel overhead is work introduced by parallel execution that is not part of the original useful computation.
- Sources include communication, synchronization, thread/process creation, scheduling, data movement, cache-coherence traffic, reductions, barriers, and idle waiting.
- Lower overhead generally improves scalability, but some overhead is necessary to coordinate parallel work.
A useful total-overhead definition is:
$$ T_o = pT_p - T_1 $$
Here, $pT_p$ is the total processor-time consumed by the parallel run, while $T_1$ is the useful work represented by the single-processor baseline.
The cost of a parallel execution is:
$$ C_p = pT_p $$
A parallel algorithm is called cost-optimal when its total cost is asymptotically comparable to the best sequential execution time.
VIII. Resource Utilization
- Resource utilization measures how much of a hardware resource is active during execution.
- Useful resources to observe include CPU cores, GPU compute units, memory bandwidth, cache capacity, network links, storage, and accelerators.
- High utilization is not automatically evidence of good performance. A processor can be 100% busy while repeatedly missing in cache, spinning on a lock, or doing unnecessary work.
- Low utilization can indicate insufficient parallelism, load imbalance, blocking I/O, synchronization, or a bottleneck elsewhere.
Resource utilization should therefore be interpreted together with throughput, latency, efficiency, and hardware-counter data.
IX. Communication-to-Computation Ratio
Parallel performance often depends on how much useful computation is performed for each unit of communication.
A conceptual ratio is:
$$ \text{CCR} = \frac{T_{\text{communication}}}{T_{\text{computation}}} $$
Lower communication-to-computation ratios are generally easier to scale. If communication grows faster than useful computation, adding processors can eventually make the program slower.
For distributed-memory systems, important communication costs include:
- Message startup latency.
- Transfer time proportional to message size.
- Network contention.
- Collective operations.
- Waiting for communication partners.
For shared-memory systems, analogous costs include:
- Cache-line transfers.
- Lock contention.
- Barrier waiting.
- False sharing.
- NUMA remote-memory access.
Amdahl's Law
Amdahl's Law, introduced by Gene Amdahl in 1967, estimates the speedup available for a fixed-size workload when only part of the program can benefit from parallel execution.
If a fraction $P$ of the execution time can be parallelized and the remaining fraction $1-P$ must execute serially, the idealized speedup on $n$ processors is:
$$ S(n) = \frac{1}{(1-P) + \frac{P}{n}} $$
Where:
- $S(n)$ is the predicted speedup using $n$ processors.
- $P$ is the fraction of execution time that can be parallelized.
- $1-P$ is the serial fraction.
- $n$ is the number of processors.
Important Points:
- The sequential portion $(1-P)$ eventually limits the benefit of adding processors.
- The parallel portion $P$ is assumed to divide ideally among the processors.
- Real programs usually perform worse than the basic formula predicts because the simple model does not explicitly include communication, synchronization, load imbalance, memory contention, or scheduling overhead.
- Diminishing returns appear as $n$ increases because $\frac{P}{n}$ becomes small while the serial fraction remains.
- For an unlimited number of processors:
$$ \lim_{n\to\infty} S(n) = \frac{1}{1-P} $$
For example, if $P=0.95$, then even infinitely many processors would give an idealized maximum speedup of:
$$ S_{\max} = \frac{1}{0.05} = 20 $$
If $P=0.99$, the corresponding limit is:
$$ S_{\max} = \frac{1}{0.01} = 100 $$
This illustrates why apparently small serial fractions become important at large processor counts.
Practical Implications:
- Reducing serial work can matter more than adding processors.
- Communication and synchronization should be considered part of the effective non-scaling portion of a real implementation.
- Optimizing a part of the program that consumes little total time has limited impact on end-to-end runtime.
- Amdahl's Law is particularly useful when evaluating strong scaling, because the total workload is fixed.
- Performance work should target the part of the program that dominates actual measured runtime, not merely the code that appears most parallelizable.
Amdahl's Law also explains why optimization must be evaluated end to end. Suppose 80% of a program is accelerated by a factor of 10 while the remaining 20% is unchanged:
$$ S = \frac{1}{0.2 + \frac{0.8}{10}} = \frac{1}{0.28} \approx 3.57 $$
Even though most of the program became ten times faster, the complete application becomes only about $3.57\times$ faster.
Visual Representation of Amdahl's Law
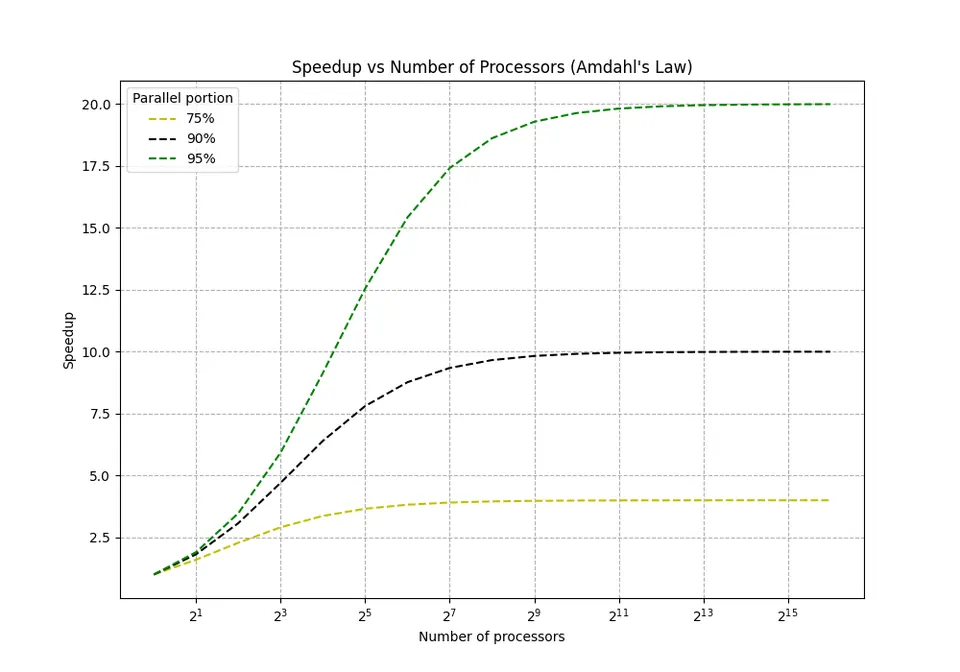
The graph illustrates the relationship between speedup on the y-axis and the number of processors on the x-axis for different values of the parallel fraction $P$. Larger values of $P$ produce better scaling, but every curve eventually bends away from ideal linear speedup because the serial fraction remains.
Amdahl's Law should not be interpreted as saying that large machines are useless. It models a fixed-size problem. In practice, larger machines are often used to solve larger problems, not only to solve the same problem faster. This is the motivation behind weak-scaling analysis and related models such as Gustafson's Law.
For a workload that grows with the number of processors, Gustafson's Law expresses scaled speedup as:
$$ S_G(p) = p - \alpha(p-1) $$
where $\alpha$ is the measured serial fraction of the scaled workload. Amdahl's and Gustafson's views answer different questions:
- Amdahl: How much faster can this fixed problem run?
- Gustafson: How much larger a problem can we solve in roughly the same time as resources grow?
Performance Measurement Techniques
Performance measurement should be systematic and reproducible. A single timing result is rarely sufficient because parallel execution is affected by scheduling, cache state, network traffic, frequency scaling, operating-system activity, and input-dependent behavior.
Before profiling or monitoring, establish a reliable measurement procedure:
- Use a representative workload and realistic input size.
- Define a clear baseline.
- Measure wall-clock time for end-to-end speedup.
- Repeat experiments and report variation, not only the best run.
- Separate warm-up effects from steady-state measurements when relevant.
- Keep hardware, software versions, compiler options, and environment variables consistent.
- Record the processor/thread count, affinity, NUMA placement, and GPU configuration.
- Measure both useful work and overhead.
- Avoid adding synchronization only for timing unless the synchronization is part of the real algorithm.
- Validate correctness after every optimization.
I. Profiling
- Profiling collects detailed information about where execution time and hardware resources are being consumed.
- Its purpose is to locate bottlenecks before attempting optimization.
- In parallel programs, the hottest function is not always the main scalability problem. Time can instead be lost in synchronization, communication, memory stalls, or load imbalance.
- Profiling should therefore examine both computation and waiting.
Important questions include:
- Which functions consume the most wall-clock or CPU time?
- Which threads or processes are idle?
- How much time is spent in locks, barriers, communication, or I/O?
- Are workers balanced?
- Is performance limited by computation or memory bandwidth?
- Are cache misses, branch mispredictions, or NUMA accesses unusually high?
- On GPUs, are kernels limited by memory bandwidth, occupancy, synchronization, or instruction throughput?
- In distributed programs, how much time is spent in MPI communication and collectives?
There are two common profiling approaches:
- Sampling periodically records the executing code and has relatively low overhead.
- Instrumentation inserts measurement points around functions or events and can provide precise call/event data, but may perturb execution more strongly.
Tools for Profiling in Parallel Computing:
| Tool | Description | Useful Features | Typical Use |
|---|---|---|---|
| gprof | Traditional GNU function profiler | Flat profile and call graph | Basic profiling of instrumented native applications compiled with -pg |
| perf | Linux performance-analysis toolkit | Sampling, hardware counters, call stacks, scheduler events | CPU hotspots, cache misses, branch behavior, context switches |
| Intel VTune Profiler | CPU and threading performance analyzer | Hotspots, concurrency, memory access, microarchitecture analysis | Thread scaling, CPU bottlenecks, memory-bound code |
| Valgrind / Callgrind | Dynamic instrumentation framework | Instruction-level profiling, call counts, simulated cache behavior | Detailed CPU investigation when high execution overhead is acceptable |
| NVIDIA Nsight Systems | System-wide CPU/GPU timeline profiler | CUDA activity, CPU threads, synchronization, kernel launches, transfers | Understanding CPU-GPU overlap and scheduling |
| NVIDIA Nsight Compute | GPU kernel profiler | Memory throughput, occupancy, instruction and warp metrics | Detailed CUDA kernel optimization |
| HPCToolkit | Performance tools for HPC applications | Sampling, calling-context profiles, CPU/GPU analysis | Large parallel applications and scaling studies |
| mpiP | Lightweight MPI profiling library | Per-call and per-rank MPI communication statistics | Identifying communication-heavy MPI code |
Steps in Profiling Parallel Programs:
- Establish a baseline. Record runtime, throughput, processor count, and important configuration details before optimization.
- Choose representative input. Small test data can hide memory, communication, and scaling bottlenecks.
- Collect a coarse profile. First determine where most time is spent before collecting very detailed data.
- Separate useful work from waiting. Distinguish computation from lock waits, barriers, communication, and I/O.
- Inspect per-worker behavior. Aggregate averages can hide one slow rank, thread, or GPU stream.
- Use hardware counters when needed. Cache misses, bandwidth, branch behavior, and stalled cycles help explain why a hotspot is slow.
- Form a hypothesis. Optimization should be based on a measured cause, such as poor locality or lock contention.
- Change one major factor at a time. This makes performance effects easier to attribute.
- Re-measure. Verify that the intended metric improved and that another bottleneck did not become dominant.
- Validate correctness. Faster incorrect code is not an optimization.
Timing Parallel Code
Timing parallel code requires care because different clocks answer different questions.
- Wall-clock time measures elapsed real time and is normally the correct metric for application speedup.
- CPU time measures processor time consumed and can increase even when wall-clock time falls.
- Per-thread or per-process timers are useful for diagnosing imbalance but should not replace end-to-end wall time.
For an MPI region, one common pattern is:
MPI_Barrier(MPI_COMM_WORLD);
double start = MPI_Wtime();

/* Parallel operation being measured */

double local_elapsed = MPI_Wtime() - start;
double elapsed;

MPI_Reduce(
    &local_elapsed,
    &elapsed,
    1,
    MPI_DOUBLE,
    MPI_MAX,
    0,
    MPI_COMM_WORLD
);
Taking the maximum process time reflects the fact that the parallel phase is not complete until its slowest participating process finishes.
The barrier in this example is appropriate only when the measurement intentionally requires aligned start times. Adding barriers that are not present in the actual algorithm can change behavior and produce an unrealistic measurement.
Strong-Scaling Experiment
A simple strong-scaling study keeps the problem fixed and measures:
| Processors | Runtime | Speedup | Efficiency |
|---|---|---|---|
| 1 | $T_1$ | $1.0$ | $100\%$ |
| 2 | $T_2$ | $T_1/T_2$ | $S_2/2$ |
| 4 | $T_4$ | $T_1/T_4$ | $S_4/4$ |
| 8 | $T_8$ | $T_1/T_8$ | $S_8/8$ |
A useful plot shows processor count against runtime, speedup, and efficiency. The point where additional processors provide little improvement is the scaling knee for that workload and configuration.
II. Monitoring
- Monitoring continuously observes a running system rather than analyzing one bounded profiling experiment.
- It is especially useful for long-running services, clusters, production pipelines, and distributed systems.
- Monitoring shows whether performance changes over time as workload, traffic, hardware health, or resource pressure changes.
Important monitoring targets include:
- CPU and GPU utilization.
- Memory use and memory bandwidth.
- Disk and network throughput.
- Queue depth and request rate.
- Application throughput.
- p50/p95/p99 latency.
- Error and retry rates.
- Worker/rank health.
- Temperature, clock throttling, and accelerator errors where relevant.
- MPI job failures or scheduler state in HPC environments.
- Container or node resource pressure in clustered environments.
High-level system metrics help identify when a problem occurs, while profilers and traces help explain why it occurs.
Tools for Monitoring in Parallel Computing
| Tool | Description | Useful Features | Typical Use |
|---|---|---|---|
| Nagios | Infrastructure and service monitoring system | Health checks, alerts, plugin ecosystem | Host and service availability |
| Prometheus | Metrics collection and time-series monitoring | Pull-based metrics, PromQL, alerting, exporter ecosystem | Application and cluster metrics |
| Grafana | Dashboard and visualization platform | Dashboards, multiple data sources, alert visualization | Visualizing Prometheus and other telemetry |
| Zabbix | Infrastructure monitoring platform | Agents, discovery, dashboards, triggers, alerting | Servers, networks, and application infrastructure |
| nvidia-smi | NVIDIA GPU management and monitoring utility | Utilization, memory use, power, temperature, process information | Quick inspection of GPU workloads |
| Slurm accounting tools | HPC scheduler/accounting interfaces | Job state, allocated resources, elapsed time, CPU/memory statistics | Cluster job monitoring and historical resource analysis |
Steps in Monitoring Parallel Systems:
- Define the service or job objectives. Decide which outcomes matter: throughput, latency, completion time, utilization, or availability.
- Select actionable metrics. Avoid collecting large quantities of data that cannot be interpreted or acted upon.
- Instrument the application. System metrics alone cannot explain application-level queueing, phases, or request failures.
- Collect per-node and aggregate data. Cluster-wide averages can hide one overloaded or failing node.
- Build dashboards around relationships. Compare request rate with latency, CPU use with throughput, or queue depth with worker utilization.
- Set meaningful alerts. Alert on symptoms that require action rather than every temporary fluctuation.
- Retain historical data. Long-term trends help identify regressions, capacity limits, and gradual resource growth.
- Correlate metrics with deployments and configuration changes. A performance regression is easier to diagnose when it can be tied to a specific change.
- Periodically review thresholds and dashboards. Workloads evolve, so useful monitoring must evolve with them.
- Use profiling after monitoring identifies a problem. Monitoring locates the time and scope of an issue; profiling provides the detailed explanation.
A useful performance workflow is therefore:
Measure baseline
      |
      v
Identify scaling or latency problem
      |
      v
Monitor system-level behavior
      |
      v
Profile the affected application or phase
      |
      v
Form and test an optimization hypothesis
      |
      v
Re-measure speedup, efficiency, and correctness
The central rule is simple: measure before optimizing, explain the bottleneck with evidence, and measure again after every meaningful change.