Files and Filesystems
In Unix, files and filesystems are important components of the operating system's structure. A file is a collection of data stored on disk, which can include anything from text documents and images to executable programs. Files are organized within directories in a hierarchical structure, allowing for efficient data management and retrieval.
A filesystem, on the other hand, is a method and data structure that the operating system uses to manage files on a disk or partition. It provides a way to store, retrieve, and organize files, supporting features like file permissions, links, and metadata. Common Unix filesystems include ext4, XFS, and Btrfs, each offering different capabilities and optimizations.
Types of Files in a UNIX Filesystem
Unix and Unix-like systems, including Linux, organize files in a hierarchical structure called a filesystem. Files can be classified based on their purpose, storage method, and visibility.
Classification Based on Purpose
- Ordinary files are the most common type, containing text, data, or program code. They cannot contain other files or directories.
- Directory files function as folders to organize other files, with the root directory (
/) being the top-level directory of the entire filesystem. Users' files are usually stored in their respective home directories, such as/home/adam/. - Device files represent hardware devices as if they were files. Block-oriented devices, like hard drives, transfer data in large blocks, whereas character-oriented devices, such as keyboards or modems, handle data one byte at a time.
- Link files serve as references to other files. Hard links are essentially duplicates of the original file and behave identically, while soft links (or symbolic links) act as indirect pointers to a file or directory, similar to shortcuts in Windows.
The file command in Linux is a powerful tool that helps identify and classify these file types by analyzing their content and structure. Below are insights on how the file command interprets and reports on these various classifications:
| Classification | file Command Example | file Command Output Example | Explanation |
|---|---|---|---|
| Text Files | file document.txt |
document.txt: ASCII text |
The file command detects text encoding (e.g., ASCII, UTF-8) or identifies binary format for executables. |
| Binary Files | file program |
program: ELF 64-bit LSB executable, x86-64, dynamically linked, interpreter /lib64/ld-linux-x86-64.so.2 |
Provides detailed information about binary files, including architecture and format. |
| Directory Files | file /home/user |
/home/user: directory |
Identified as a "directory". Contains pointers to other files and directories. |
| Block Devices | file /dev/sda |
/dev/sda: block special |
The file command distinguishes between block devices (e.g., "block special") and character devices (e.g., "character special"). |
| Character Devices | file /dev/tty |
/dev/tty: character special |
Useful for identifying the type of device a file represents. |
| Symbolic Links | file /usr/bin/python |
/usr/bin/python: symbolic link to /usr/bin/python3.8 |
Symbolic links are reported with their target file or directory. |
| Hard Links | file hardlinkfile |
(Output identical to the original file) | Hard links are identical to the original file in the file command output. |
Classification Based on Storage
- Regular files contain text, data, or program code and are stored directly in the file system.
- Virtual files provide an interface to other programs or the kernel. They do not contain traditional data but rather information about processes and system parameters, typically found in directories like
/procand/sys. - Remote files are stored on a remote Network File System (NFS) server. They can be accessed and manipulated as if they were stored locally.
The table below provides the most effective commands for identifying each type of file based on their specific attributes and locations:
| Classification | Command Example | Command Output Example | Explanation |
|---|---|---|---|
| Regular Files | file document.txt |
document.txt: ASCII text |
The file command detects the type of content in regular files, such as text, binary, or executable. |
| Virtual Files | stat /proc/cpuinfo |
File: /proc/cpuinfo\nSize: 0\tBlocks: 0\tIO Block: 4096 regular file\nDevice: 0,5\tInode: 4026532255 |
The stat command shows a typical file size of 0, located in /proc or /sys, indicating it's a virtual file. |
| Remote Files | df -T /mnt/nfs/remote_file |
Filesystem Type 1K-blocks Used Available Use% Mounted on\nnfsserver:/export nfs 1024000 102400 924000 10% /mnt/nfs |
The df -T command displays the filesystem type as nfs, identifying it as a remote file on an NFS server. |
Classification Based on Visibility
- Visible files are displayed when you list the contents of a directory using commands like
ls. - Hidden files are not displayed in a standard directory listing. They start with a period (
.) and typically store configuration data or system files. They can be revealed using thels -acommand.
Filenames are case-sensitive. This means the operating system treats "Test," "TEST," and "test" as different files. Also, most file types in Linux are determined by file content and not by the file extension, unlike systems like Windows.
Special Directory Names
In a filesystem, certain directory names have special meanings that simplify navigation and file management:
- The
./notation refers to the current directory, meaning the directory where you are presently located. It is commonly used when executing a script or a program located in the current directory. For instance, if you have a script namedscript.shin the current directory, you can run it using./script.sh. This tells the system to look forscript.shin the current directory. - The
../notation refers to the parent directory, which is the directory one level up from the current directory in the filesystem hierarchy. It is useful for navigating upwards in the directory structure. For example, if you are in/home/user/Documentsand you usecd ../, you will move up to/home/user. - The
~/notation is a shorthand for the current user's home directory. The home directory is a personal space allocated to a user where personal files and settings are stored. For example,~/Documentswould refer to theDocumentsdirectory within the home directory of the current user. This is especially useful for referencing files and directories in a user's home space without needing to specify the full path.
Blocks, Superblocks & Pages
Blocks, pages, and the superblock are concepts in storage and memory management. A block is the smallest unit of data on disk used by file systems, while a page is the smallest unit of memory used in RAM by the operating system. The superblock holds metadata about the file system, such as its size and structure. While blocks manage how files are stored, pages manage how memory is accessed, and the superblock helps the system organize everything.
Block — the Atomic On-Disk I/O Unit
Entire Disk (logical view divided into 4 KiB blocks)
┌────────────────────────────────────────────────────────────────────────┐
│ Block 0 │ Block 1 │ … │ Block 41 │ Block 42 │ Block 43 │ … │ Block N-1 │
└────────────────────────────────────────────────────────────────────────┘
                   ↑
                   │
            Single 4 KiB Block
Offset 0     ┌───────────────────────────────────┐  Offset 4095
             │          DISK BLOCK #42           │
└───────────────────────────────────┘- Fixed size chosen at
mkfs(e.g. ext4 default = 4 KiB). - All filesystem metadata/data (bitmaps, inodes, journals) is laid out in whole blocks.
- The block device layer (
bio) can aggregate multiple blocks into one I/O.
Superblock → Group Descriptor Table → Block Groups
Filesystem Layout (ext4, 4 KiB blocks)
LBA 0           LBA 124      LBA 125                      LBA 126+
┌──────────┬─────────────┬────────────────────┬──────────────────────────┐
│ Boot     │ Padding     │ Primary Superblock │ Group Descriptor Table   │
│ Sector   │ (blocks)    │ (block 1024)       │ (blocks 1025…1025+GDT)   │
└──────────┴─────────────┴────────────────────┴──────────────────────────┘
                                  │
                                  ▼
              ┌───────────────────────────────────────────┐
              │ GDT Entry #2 (for Block Group #2)         │
              │  • start_block = 17,000                   │
              │  • free_blocks, free_inodes, flags…       │
└───────────────────────────────────────────┘- Superblock (at block 1024) holds global FS metadata plus a pointer (offset) to the start of the Group Descriptor Table (GDT).
- GDT is an array of one descriptor per block group; each descriptor records where that group begins, how many free blocks/inodes remain, etc.
- When the kernel needs to read a block group’s metadata, it indexes into the GDT to find its on-disk location.
Block Group Layout (≈128 MiB @ 4 KiB blocks)
Descriptor #2
    ↓
Block Group #2 Start
┌───────────────────────────────────────────────────────────────────┐
│ Inode Bitmap    [1 block]                                         │
├───────────────────────────────────────────────────────────────────┤
│ Block Bitmap    [1 block]                                         │
├───────────────────────────────────────────────────────────────────┤
│ Inode Table     [ (InodesPerGroup×InodeSize)/BlockSize blocks ]   │
├───────────────────────────────────────────────────────────────────┤
│ Data Blocks     [remaining blocks: actual file data]              │
└───────────────────────────────────────────────────────────────────┘
                         ↑
                         │
Block #42 ← lives here, inside this group’s Data Blocks- Inode & Block Bitmaps: track which inodes/blocks are free or in use.
- Inode Table: fixed number of inodes allocated per group.
- Data Blocks: the lion’s share of the group, holding file contents and directory structures.
- When you ask to read or write block 42, the filesystem:
- Looks up block group via
42 / blocks_per_group→ group index. - Indexes into the GDT to get that group’s starting block.
- Computes the offset within the group to reach block 42.
- Looks up block group via
Inode & Extent Trees
Every file is represented by an inode, which points to extents—contiguous block runs—that efficiently map file data on disk.
                    INODE #132 (regular file)
┌──────────────────────────────────────────────────────────────┐
│ mode, uid, size, mtime, …  |  EXTENT ROOT → depth = 1        │
└──────────────────────────────────────────────────────────────┘
                               │
                 ┌─────────────┴─────────────┐
                 ▼                           ▼
        EXTENT (logical 0-255)       EXTENT (logical 256-511)
     ┌───────────────────────┐     ┌───────────────────────┐
     │ start = 8200, len=256 │ ... │ start = 8456, len=256 │
└───────────────────────┘ └───────────────────────┘- 1 inode ↔ 1 file/dir.
- Extents record contiguous physical block runs ⇒ bitmap compression, faster I/O submit, no indirect block b-tree lookup for large files.
- Up to 4 extents inline in the inode; spill into extent index blocks when needed (depth ≤ 5 supports files ≈ 8 EiB).
Directory Entries (dentry blocks)
Directories are special files containing entries that map names to inode numbers. ext4 accelerates lookups with a hash-tree index for large directories.
DIR DATA BLOCK
┌── inode=2048 │ "config" │ rec_len  │ file_type ──┐
│   ...        │ "lib"    │          │             │
└── inode=2050 │ "logs" │ │ END … ┘- Dir-files are just blocks of
(inode#, name, type)pairs → ordinary read(2)/write(2) paths apply. htreeindex (ext4 dir_index) upgrades large dirs to O(log n) lookup.
Journal (Ordered Mode)
The journal provides write-ahead logging for metadata (and optionally data) to ensure filesystem consistency across crashes.
RESERVED JOURNAL AREA
┌────────────────────────────────────────────────────┐
│  Descriptor → [block #42, block #99, …]            │
│  Data payloads (shadow copies)                     │
│  Commit block (checksum + tid)                     │
└────────────────────────────────────────────────────┘- Write-ahead log capturing metadata (and optionally data) before main-area overwrite.
- Ext3/4 default ordered mode: data blocks reach media before the commit → no fs-checker sees stale metadata.
- Replayed by
jbd2on mount after unclean shutdown.
End-to-End Walk-Through
Here’s a high-level sequence tracing a read from the superblock through the block group into actual file data.
[ Superblock ] → [ Group #0 bitmaps ] → [ Inode #132 ] → [ Extent 8200..8455 ] → [ File Data ]From Disk Blocks → RAM Pages (Unified Page Cache)
Once blocks are read from disk, they enter the unified page cache, serving both file I/O and memory mappings seamlessly.
+----------------------------------+
|  FILE -> mapping (address_space) |
+----------------------------------+
	        │
read(2)/mmap    │        writeback
	        ▼
RAM phys addr 0x3f7e_0000
┌──────────────────────────────┐ 4 KiB PAGE
│  page->mapping  -> inode132  │───┐  state: Clean / Dirty
│  index = 2 (→ block #8202)   │   │
└──────────────────────────────┘   │
		                   │ DMA/PIO
                       ┌───────────┴───────────────────┐
	               │        DISK BLOCK #8202       │
└───────────────────────────────┘- Fault-on-first-touch: VFS sees a cache miss, allocates a free page, submits
bioto read the 4 KiB block. - Subsequent I/O hits the in-RAM page; mmap’d code/data benefit identically — the cache is unified across read(), mmap(), readdir, etc.
- Indexing:
page->index = logical_block_numberallows constant-time lookup in radix-tree/xarray.
Dirty Pages → Write-back Pipeline
Modifications to pages become "dirty" and are eventually written back to disk in optimized batches by the kernel’s write-back machinery.
USER SPACE write(2) / memcpy to mmap
            │                     flusher thread / sync(2)
            ▼                                   │
   page->flags |= DIRTY                         │
            │                                   ▼
 ┌──────────┴────────────────┐       bio / blk-mq layer
 │  ext4_writepages() merges │  ─────────────────────────►  Media
└───────────────────────────┘- Dirty clustering (
writepages()): adjacent dirty pages coalesced into single bio up to the devicequeue_max_hw_sectors. - pdflush / bdi flusher wakes when
vm.dirty_ratioordirty_expire_centisecsthresholds fire. sync,fsync,O_SYNC, and journal commit barriers guarantee persistence semantics demanded by databases and userspace logs.
Directory Hierarchy
Linux follows the Filesystem Hierarchy Standard (FHS): everything, including devices and running processes, lives somewhere under a single root directory /. This predictability lets administrators and software know exactly where to look for binaries, configuration files, logs, and users’ data.
/
├── bin/          → Core user commands (ls, cp)
├── boot/         → Kernel, initramfs, bootloader
├── dev/          → Device nodes (sda, tty0, random)
├── etc/          → System-wide configuration
│   ├── network/  → Networking configs
│   └── ssh/      → OpenSSH server & client settings
├── home/
│   └── <user>/   → Personal files & dotfiles
│       ├── Desktop/  ─┐
│       ├── Documents/ ├─ XDG-defined user dirs
│       └── …          ┘
├── lib/          → Shared libs for /bin & /sbin
├── media/        → Auto-mount points (USB, DVD)
├── mnt/          → Temporary/manual mounts
├── opt/          → Optional add-on software
├── proc/         → Kernel & process pseudo-FS
├── root/         → Superuser’s home (not “/”!)
├── run/          → Volatile runtime data (PID files)
├── sbin/         → Core system binaries (fsck, ip)
├── srv/          → Data served by daemons (HTTP, FTP)
├── sys/          → Kernel objects (sysfs pseudo-FS)
├── tmp/          → World-writable temp space, cleared on reboot
├── usr/
│   ├── bin/      → Non-essential user programs
│   ├── lib/      → Libraries for /usr/bin
│   ├── sbin/     → System binaries not needed for early boot
│   └── local/    → Admin-installed software (keeps pkg-mgr clean)
└── var/
    ├── cache/    → Application caches (dnf, apt)
    ├── log/      → System & service logs
    ├── mail/     → Local mail spools
    └── tmp/      → Persistent temp data between reboots
Quick-Reference Table:
| Directory | Typical Contents | Why It Matters |
|---|---|---|
/ |
The root of everything | Removing this directory—or mounting the wrong thing over it—renders the OS unusable. |
/bin, /sbin |
Crucial commands and their companions (shell, cp, mount, fsck) | Must be available early in boot and in single-user/emergency mode. |
/usr/{bin, sbin, lib} |
The bulk of user-space packages | Can be mounted read-only or even on a separate partition; not needed until the kernel hands control to init. |
/lib |
Loader (ld-linux) and libc-style libraries |
Without it, nothing in /bin or /sbin executes. |
/etc |
Human-readable config files | Convention: one file per service (e.g., ssh/sshd_config). Avoid binaries or large data here. |
/var |
Changing data: logs, queues, databases | Grows over time—monitor disk usage here first. |
/home |
Users’ personal space | Keep on its own partition to let OS upgrades/re-installs leave user data untouched. |
/proc, /sys, /run |
Kernel-generated pseudo filesystems | Expose live system state; no actual data on disk. |
/opt, /usr/local |
Third-party or locally built apps | Keeps them separate from distro-managed packages—ideal for self-compiled software. |
/media, /mnt |
Mount points | /media is auto-managed by udev/udisks; /mnt is for you to mount test filesystems quickly. |
/root |
The root user’s home | Allows root to function in rescue mode when /home might not be available. |
/boot |
Kernel(s), GRUB, EFI stubs | Often on its own small, unencrypted partition so the firmware can read it. |
- Placing
/home,/var, and/usron separate partitions can improve security and recovery options. - Directories like
/proc,/sys, and/runchange dynamically—never store persistent files there. /tmpis world-writable (+t sticky bit) and routinely wiped at boot; use/var/tmpif you need temp files that survive reboots.- Don’t scatter personal scripts in
/usr/bin; instead use/usr/local/binor add a custom directory (e.g.,~/bin) to your$PATH. - Most mainstream distros adhere closely to the FHS, but container images and embedded systems may simplify or rearrange parts of the hierarchy.
File System Types
A file system is a method of organizing, storing, and retrieving data on a storage device, like a hard drive, SSD, or USB drive. It manages the available space on the device, keeping track of which sectors belong to which files and directories.
Several types of file systems can be used on Linux systems, each designed with specific use-cases and features:
- The ext2 (Second Extended Filesystem) is among the first file systems crafted specifically for Linux, and while it is efficient, it lacks advanced features like journaling or encryption.
- An improved version of ext2, ext3 (Third Extended Filesystem), includes support for journaling, which helps protect against data loss by maintaining a log of changes that are yet to be committed to the file system.
- Currently the default Linux file system, ext4 (Fourth Extended Filesystem) supports larger file sizes and file systems, provides improved performance and reliability, and includes features such as delayed allocation and journal checksumming.
- Originally developed by IBM, the JFS (Journaled File System) is optimized to handle large file systems efficiently and includes journaling capabilities.
- The NFS (Network File System) is not a traditional file system but rather a protocol that allows a system to access files over a network as though they were on its local hard drive.
- Serving as a software layer in the kernel, the VFS (Virtual File System) provides a common interface to various file systems, enabling the operating system to uniformly access and manage different types of file systems.
- The FAT (File Allocation Table) system is simple and widely used, particularly on removable storage devices, making it a suitable choice for interoperability across various operating systems.
- A standard for Windows NT and its later versions, NTFS (New Technology File System) can be accessed on Linux but is not native, which may result in a lack of full functionality.
- Known for its strong performance and reliability, ReiserFS (Reiser File System) is a general-purpose, journaled file system that efficiently handles large numbers of small files, making it a popular choice on servers.
- The Btrfs (B-tree File System) is a copy-on-write (CoW) file system for Linux, designed to provide advanced features focused on fault tolerance, repair, and simplified administration, with capabilities like snapshots, subvolumes, and built-in RAID.
- Developed by Silicon Graphics, Inc., XFS is a high-performance, journaling file system that excels at parallel I/O, making it particularly effective for applications involving large files that require high-performance I/O operations.
| Category | ext2 | ext3 | ext4 | JFS | NFS | VFS | FAT | NTFS | ReiserFS | Btrfs | XFS |
|---|---|---|---|---|---|---|---|---|---|---|---|
| Design Purpose | Simple Linux file system | Improved ext2 with journaling | Default Linux file system | Large file systems | Network file access | Common interface for FS | Removable storage | Windows file system | Small files, servers | Advanced Linux features | High-performance, large files |
| Journaling | No | Yes | Yes | Yes | N/A (protocol) | N/A | No | Yes | Yes | Yes | Yes |
| Performance | Efficient for small FS | Better than ext2 | Better than ext3 | High efficiency | Depends on network | N/A | Simple, lower performance | Good, Windows optimized | Good for small files | Good, advanced features | Excellent, parallel I/O |
| Maximum File/FS Size | Smaller than ext3/4 | Larger than ext2 | Very large | Very large | N/A | N/A | Limited by design | Very large | Large | Very large | Very large |
| Suitability | Basic, older Linux systems | General Linux use | Modern Linux systems | Enterprise, large data | Network environments | Kernel-level operations | Wide compatibility | Windows environments | Server use | Linux, advanced use | Large file handling |
| Encryption Support | No | No | Yes (since 4.1) | No | N/A | N/A | No | Yes | No | Yes | No |
| Data Recovery | Harder | Easier than ext2 | Easier than ext3 | Good | Depends on implementation | N/A | Simpler but riskier | Good | Good | Very good | Good |
| Use in Large Servers | Less common | Common | Very common | Yes | Yes, for shared storage | N/A | Less common | Less common | Yes | Yes | Yes |
| Use in Personal Devices | Less common | Less common | Common | Less common | Less common | N/A | Very common | Common in Windows | Less common | Growing | Less common |
Why And When Would You Care About File System?
Knowledge about the file systems is important when you need to make sure that data is stored, accessed, and maintained efficiently, and you should care about them when your applications need to handle simultaneous operations and manage large volumes of files. They become relevant in scenarios where multiple processes perform reading or writing tasks concurrently, where limitations on the number of files and directory entries may affect scalability, and where factors such as disk fragmentation or space constraints can impact overall performance. Understanding how systems like NTFS, ext4, and FAT32 differ can help in selecting the appropriate storage solution and ensuring that mechanisms like concurrent access work reliably under varying load conditions.
Concurrency and File Access:
- Modern file systems allow multiple processes to access a file concurrently without interruption, and their support for concurrent reading enables efficient data retrieval.
- Concurrent operations, in which one process writes while another reads a file, may lead to inconsistent data access, and this situation exemplifies a potential read-write conflict.
- When multiple processes perform write operations on the same file simultaneously without proper locking, the file may become corrupted, and this risk underscores the challenge of simultaneous writing.
Below is what the current public benchmark record shows when you compare today’s Linux files-systems on a single NVMe SSD or SATA SSD with their default mount options and no exotic tuning.
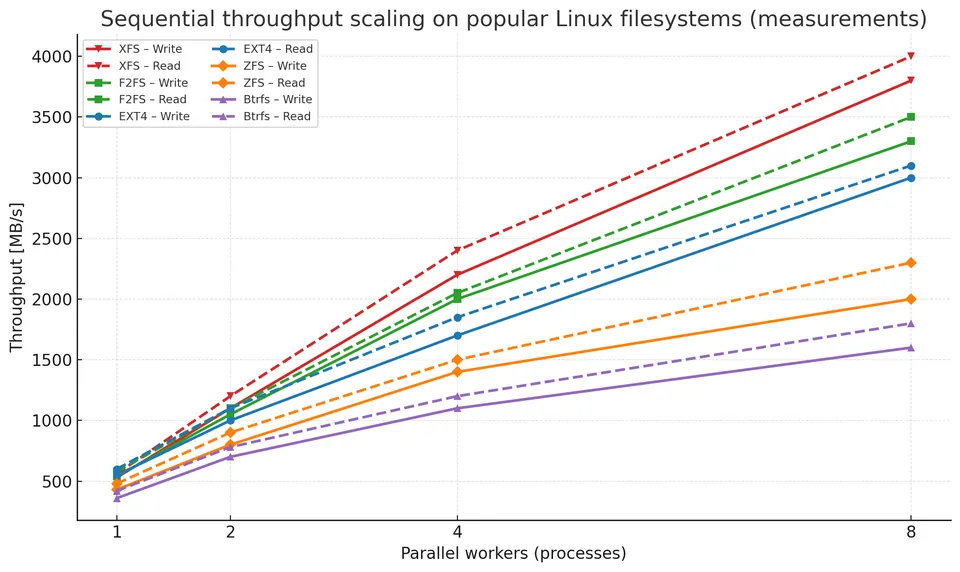
- EXT4 edges out XFS with a single thread, but
- XFS scales hardest once you pass ≈2 parallel writers/readers thanks to its per-allocation-group design — by eight workers it’s \~25 % faster than EXT4.
- F2FS slots in between: flash-optimised and quick at low-to-mid thread counts, but it can’t quite keep up with XFS’s metadata parallelism at the top end.
- ZFS and Btrfs trail because CoW, checksums and copy-on-write write-amplification cost throughput, especially as queue depth rises.
- With default settings on a single drive, EXT4 is measurably faster than both Btrfs and ZFS, and the public data going back years backs that up. But the moment you start using the advanced features that motivated those filesystems in the first place, their performance story changes—and sometimes surpasses EXT4 in the process.
File Limits:
- The FAT32 file system supports up to 268,173,300 files per volume, which outlines its capacity constraints for file storage.
- The NTFS file system can handle up to 4,294,967,295 files per volume, ensuring a larger capacity for file management.
- The ext4 file system also supports up to 4,294,967,295 files per volume, making it useful for environments that require managing many files.
- Operating systems typically restrict the number of files a process can have open at one time, and Linux systems often permit 1024 open files per process by default while allowing this limit to be increased.
Directory Limits:
- The FAT32 file system permits up to 65,535 files per directory when using short (8.3) filenames, setting a defined upper boundary for individual directories.
- The ext4 file system can efficiently manage up to 10 million files per directory, although performance may decrease as the file count grows.
- Directory size is determined by the file system's structure, and in FAT32, each short filename entry occupies 32 bytes, capping a directory’s capacity at 2,097,152 bytes.
Space and Performance Considerations:
- File fragmentation occurs when a file’s data is stored in non-sequential parts on disk, and this fragmentation effect can lead to slower data access.
- Intensive file operations may consume extensive disk space, and monitoring disk usage is useful for avoiding shortages that could disrupt system operations.
File System Limits:
- Different file systems impose varying maximum file sizes, and the FAT32 file system limits individual files to 4 GiB minus 1 byte while NTFS and ext4 accommodate larger files.
- File name length limitations differ by file system, and NTFS allows filenames up to 255 characters in length compared to the shorter naming format of FAT32.
Concurrent Reading and Writing Considerations:
- When multiple processes write to the same file without proper synchronization, the risk of data corruption increases, and implementing file locking helps mitigate this risk.
- If one process writes to a file while another reads from it, incomplete or inconsistent data may be accessed, and managing read-write operations carefully is advisable.
Scaling Issues with File Systems:
- Handling millions of write operations per minute necessitates a high-performance file system, and effective I/O management is required to support such throughput.
- Distributed file systems are designed to manage extensive storage and high throughput, and they offer scalable solutions for large-scale data operations.
File System Choices:
Local file systems generally offer lower latency compared to network file systems, and network protocols such as NFS or SMB may encounter challenges with network file locking that affect access performance.
Managing File Systems
Managing file systems is a fundamental skill that involves various operations such as checking existing file systems, installing necessary tools, creating new file systems on fresh partitions or drives, and modifying existing ones. This comprehensive guide provides detailed steps for each of these tasks, complete with commands, expected outputs, and practical considerations.
Checking Existing File Systems
Before performing any file system operations, it's important to have a clear understanding of the current state of your system. This helps in planning safe modifications and identifying any issues that might impact disk usage and performance.
I. List Mounted File Systems
Use the df -T command to display all mounted file systems along with their types. This command provides an overview of disk space usage across all mounts and the file system types used, which is helpful for troubleshooting and system monitoring.
df -TExpected Output:
Filesystem     Type     1K-blocks     Used Available Use% Mounted on
/dev/sda1      ext4      492G  215G  253G  46% /
udev           devtmpfs   16G     0   16G   0% /dev
tmpfs tmpfs 3.2G 1.3M 3.2G 1% /run- The output shows each file system along with its type (e.g.,
ext4,devtmpfs,tmpfs). - Columns such as 1K-blocks, Used, and Available provide details about total capacity, how much of it is currently used, and what remains free.
- The Use% column indicates how full each file system is, which is vital for capacity planning and identifying potential issues due to low disk space.
- The Mounted on column displays the directories where each file system is attached, giving insight into the system's directory structure and organization.
II. List Block Devices with File System Information
The lsblk command with the -f option lists all block devices and includes detailed file system information such as file system type, label, UUID, and mount points. This command is useful for understanding the hardware-level layout of storage devices and how partitions are organized.
lsblk -fExpected Output:
NAME   FSTYPE LABEL    UUID                                 MOUNTPOINT
sda
├─sda1 ext4   rootfs   a1b2c3d4-e5f6-7890-abcd-ef1234567890 /
├─sda2 ext4   home     12345678-90ab-cdef-1234-567890abcdef /home
└─sda3 swap 1a2b3c4d-5e6f-7890-abcd-ef1234567890 [SWAP]- The tree structure (using characters like ├─ and └─) visually represents how partitions (e.g., sda1, sda2, sda3) are organized under the main device (
sda). - Each partition’s file system type is shown (such as
ext4for typical Linux partitions andswapfor swap space). This helps in identifying the purpose of each partition. - Labels like
rootfsandhomehelp to quickly identify the purpose of partitions, while UUIDs provide unique identifiers, which are critical for consistent mounting across reboots. - The mount points indicate where in the directory tree each partition is accessible. The [SWAP] designation shows that a partition is designated for swap space, which is used to support system memory management.
III. Check Supported File Systems
To list all file systems currently supported by the kernel, use the following command. This command reads the /proc/filesystems file and outputs the file systems that your kernel can mount. This is useful for verifying compatibility with different file system types before attempting to mount or format new devices.
cat /proc/filesystemsExpected Output:
nodev   sysfs
nodev   tmpfs
nodev   bdev
        ext3
        ext4
        vfat
xfs- The output lists both pseudo file systems (marked with
nodev) and physical file systems (those withoutnodev), showing the range of file systems your kernel currently recognizes. - Entries like
sysfsandtmpfsare not associated with actual disk storage but represent dynamic or temporary file systems, crucial for system operations. - The supported file systems such as
ext3,ext4,vfat, andxfsindicate what types of file systems you can work with. This knowledge is important when configuring new storage devices or troubleshooting compatibility issues. - Being aware of supported file systems helps in planning for future upgrades or migrations, ensuring that the system remains stable and utilizes the most appropriate file system for its workload.
Ensuring File System Support
Before creating a new file system, ensure that your system has the necessary support for it. This involves checking for kernel module support, installing the required utilities, and verifying that your system is compatible with the file system you intend to use.
I. Check Kernel Support
To confirm that your kernel supports the desired file system, check if the module is loaded:
lsmod | grep xfsIf the output includes lines referencing xfs, it indicates that the XFS module is loaded. If no output appears, the module isn’t loaded and may need to be installed or enabled.
II. Install File System Utilities
Once kernel support is confirmed, install any necessary tools. For example, to manage the XFS file system, you need the xfsprogs package:
sudo apt update
sudo apt install xfsprogs
Expected Output:
Reading package lists... Done
Building dependency tree
Reading state information... Done
The following NEW packages will be installed:
  xfsprogs
...
Setting up xfsprogs (5.4.0-1ubuntu2) ...
This output indicates that xfsprogs has been successfully installed, and you can now proceed with XFS-specific file system tasks.
Verify Compatibility
Ensure that your system’s kernel and hardware support the file system by checking the module information:
modinfo xfsExpected Output:
This command provides details on the XFS module, including its dependencies, supported versions, and any required firmware. Reviewing this information confirms compatibility with your current setup.
Identifying the Device
Accurate identification of the target device is crucial to avoid modifying the wrong disk, which could result in data loss. These commands will help you list and inspect block devices.
I. List All Block Devices
To get an overview of all attached storage devices, use:
lsblkExpected Output:
NAME   MAJ:MIN RM  SIZE RO TYPE MOUNTPOINT
sda      8:0    0  100G  0 disk
└─sda1   8:1    0   50G  0 part /
sdb      8:16   0  200G  0 disk
└─sdb1   8:17   0   50G  0 part /mnt/data
The lsblk output lists all block devices and their partitions, along with their sizes and mount points. This lets you identify the device you intend to work with (e.g., /dev/sdb).
II. Detailed Device Information
To gather further details about each device and its partitions, use fdisk:
sudo fdisk -lExpected Output:
Disk /dev/sdb: 100 GiB, 107374182400 bytes, 209715200 sectors
Units: sectors of 1 * 512 = 512 bytes
...
This output provides detailed information on each disk, including size, sector count, and partitioning scheme. Use this to confirm the correct device before making any modifications.
III. Identify Unpartitioned Space
If your target device is new and unpartitioned, you’ll need to partition it first. Use fdisk, gdisk, or parted to create new partitions.
Unmounting the Device (if applicable)
Before modifying a device, it’s essential to ensure that it is not in use. Unmounting prevents accidental data corruption during the process.
I. Check if the Device is Mounted
Determine if the target device is currently mounted:
mount | grep sdb1Expected Output:
/dev/sdb1 on /mnt/data type xfs (rw)If the output lists the device, it means it’s mounted. Note the mount point (e.g., /mnt/data) so you can unmount it in the next step.
II. Unmount the Device
Unmount the device before making any changes:
sudo umount /dev/sdb1Expected Output:
No output indicates the device was unmounted successfully.
III. Handle Busy Devices
If you encounter a “device is busy” error, identify processes using the device:
sudo lsof /dev/sdb1Expected Output:
The output lists any processes using the device. For example:
COMMAND   PID USER   FD   TYPE DEVICE SIZE/OFF NODE NAME
bash     1234 user cwd    DIR   8,17    4096   2 /mnt/data
Terminate these processes or stop the services to release the device, allowing it to be unmounted.
Creating a File System
Once the target device is unmounted, you can proceed with creating the new file system. The file system type you choose will depend on factors like performance, reliability, and feature support.
I. Choose the File System Type
Select a file system type that meets your needs. For example, ext4 is commonly used for general-purpose storage due to its balance of performance and features. Alternatively, you may choose xfs for large filesystems or high-performance needs.
II. Create the File System
To format the device with a specific file system type, use the appropriate mkfs command. For ext4, for instance:
sudo mkfs.ext4 /dev/sdb1Expected Output:
mke2fs 1.45.5 (07-Jan-2020)
/dev/sdb1 contains a ext4 file system
Proceed anyway? (y,N) y
Creating filesystem with 26214400 4k blocks and 6553600 inodes
Filesystem UUID: 123e4567-e89b-12d3-a456-426614174000
Superblock backups stored on blocks:
	32768, 98304, 163840, 229376, 294912, ...

Allocating group tables: done
Writing inode tables: done
Creating journal (131072 blocks): done
Writing superblocks and filesystem accounting information: done
This output shows the mkfs process. It provides details on block allocation, journal creation, and the UUID for the new file system. If asked to proceed, type y to continue. Successful completion indicates the file system is now ready for use.
3. Label the File System (Optional)
Assigning a label to your file system makes it easier to identify, especially when managing multiple disks. To label an ext4 file system:
sudo e2label /dev/sdb1 mydataNo output means the label was applied successfully. You can verify the label by running sudo e2label /dev/sdb1.
Changing Existing File Systems
Modifying existing file systems requires extra caution. Backup any essential data before proceeding to avoid data loss. Here are common operations:
I. Resizing a File System
To resize a file system, unmount it first:
sudo umount /dev/sdb1Then, adjust its size. For example, to shrink an ext4 file system to 50 GB:
sudo resize2fs /dev/sdb1 50GExpected Output:
resize2fs 1.45.5 (07-Jan-2020)
Resizing the filesystem on /dev/sdb1 to 13107200 (4k) blocks.
The filesystem on /dev/sdb1 is now 13107200 (4k) blocks long.
This output confirms the new size of the file system. Note that shrinking can cause data loss if the specified size is smaller than the amount of data stored on the partition.
II. Converting File Systems
Some file systems support in-place conversions. For example, converting ext2 to ext3 to enable journaling can be done as follows:
sudo tune2fs -O has_journal /dev/sdb1Expected Output:
tune2fs 1.45.5 (07-Jan-2020)
Setting filesystem feature 'has_journal'
Creating journal inode: done
This filesystem will be automatically checked every 29 mounts or 180 days, whichever comes first.  Use tune2fs -c or -i to override.
This output shows that journaling has been enabled on the file system. This feature enhances data integrity but may slightly reduce performance.
3. Backup Before Changes
Backing up important data is always recommended before altering file systems. Tools like rsync, tar, or dd can be used for this purpose. For example:
sudo rsync -av /mnt/mydata/ /mnt/backup/Mounting the New File System
To make the new file system accessible to your system, you’ll need to mount it. Mounting allows you to interact with the file system and its contents.
1. Create a Mount Point
Choose a directory to serve as the mount point. If the directory does not exist, create it with:
sudo mkdir -p /mnt/mydataExpected Output:
No output indicates successful directory creation.
2. Mount the File System
Once the mount point exists, mount the file system:
sudo mount /dev/sdb1 /mnt/mydataExpected Output:
There’s no output if the mount is successful. You can verify by listing mounted file systems or checking the mount point with df.
3. Verify the Mount
To confirm that the file system is mounted correctly, use:
df -h /mnt/mydataExpected Output:
Filesystem      Size  Used Avail Use% Mounted on
/dev/sdb1        99G   60M   94G   1% /mnt/mydata
The output shows disk usage information for /dev/sdb1, confirming it is mounted on /mnt/mydata. You’re now ready to use the new file system for storage or data operations.
Additional Considerations
When working with file systems, automating mounting, ensuring file system health, and managing permissions are essential practices. Here’s how to handle these additional considerations.
I. Automate Mounting at Boot
To ensure your new file system is automatically mounted at system startup, add it to the /etc/fstab file.
First, edit the file:
sudo nano /etc/fstabAdd the following line to the end of the file (replace the UUID and mount point as needed):
UUID=123e4567-e89b-12d3-a456-426614174000 /mnt/mydata ext4 defaults 0 2Entry Components:
- The UUID is a unique identifier for the partition, which can be obtained using the
blkidcommand, ensuring precise identification of the partition across reboots. - /mnt/mydata is the mount point, specifying the directory where the partition will be accessible once mounted.
- The ext4 refers to the file system type, indicating how data is organized on the partition, with
ext4being a common choice for Linux systems. - defaults are the mount options, which typically include settings like read-write access and automatic mounting during startup.
- A value of 0 means the partition will skip the dump backup process, as backups are not required for this entry.
- The 2 indicates the order in which
fsckperforms checks on the partition, with2meaning it will be checked after the root partition, providing structure for file system checks.
Find the UUID for the device by running:
sudo blkid /dev/sdb1Expected Output:
/dev/sdb1: UUID="123e4567-e89b-12d3-a456-426614174000" TYPE="ext4"This output provides the UUID for /dev/sdb1. Use this identifier in the /etc/fstab entry to avoid issues if device names change on reboot. After adding this to /etc/fstab, the system will automatically mount the file system at /mnt/mydata on startup.
II. File System Maintenance
Keeping your file system healthy and monitored is crucial for data integrity and performance.
Check for Errors:
Use fsck to check the file system for errors and repair any issues.
sudo fsck /dev/sdb1Expected Output:
fsck from util-linux 2.34
e2fsck 1.45.5 (07-Jan-2020)
/dev/sdb1: clean, 10/6553600 files, 262144/26214400 blocks
This output confirms that the file system check is complete. If fsck finds no errors, it will indicate that the file system is clean. If it detects issues, fsck will attempt to repair them based on the options you specify.
Monitor Disk Usage:
Regularly monitor available space and usage with:
df -hExpected Output:
Filesystem      Size  Used Avail Use% Mounted on
/dev/sdb1        99G   60M   94G   1% /mnt/mydata
This output shows disk usage for all mounted file systems, including the newly created one. Use this information to ensure the file system has enough space for your needs.
III. Permissions and Ownership
To control who can access your mounted file system, set ownership and permissions.
Change ownership to a specific user and group:
sudo chown user:group /mnt/mydataNo output means the command succeeded.
Set permissions:
sudo chmod 755 /mnt/mydataAgain, no output indicates success.
These commands set the ownership of /mnt/mydata to a specified user and group. The chmod command assigns permissions, where 755 means the owner has read, write, and execute permissions, while others have read and execute only.
IV. Security Considerations
When storing sensitive data, consider additional security measures, such as encryption and access control.
Encryption:
Use LUKS (Linux Unified Key Setup) to encrypt the partition:
sudo cryptsetup luksFormat /dev/sdb1Expected Output:
WARNING!
========
This will overwrite data on /dev/sdb1 irrevocably.

Are you sure? (Type uppercase yes): YES
Enter passphrase for /dev/sdb1:
Verify passphrase:
LUKS prompts for confirmation before encrypting the partition. Follow the prompts to set a passphrase, which will be required for future access.
Access Control (ACL):
To set fine-grained permissions, enable and configure Access Control Lists (ACLs). For example, to grant a user read access:
sudo setfacl -m u:username:r /mnt/mydataNo output, indicating success.
This command grants username read-only access to /mnt/mydata. Use getfacl to verify ACLs or to modify permissions for other users as needed.
Challenges
- Can you explain what the root directory is in Linux? How is it different from the root user's home directory?
- In the context of the
echocommand in Linux, what is the relationship between/bin/echoand typingechoat the shell prompt? - Using
/dev/randomor/dev/urandom, how would you create a file filled with 100 lines of random characters? Can you write a shell command to do this? - What is the purpose of the
/binand/sbindirectories in a Linux system? Can you list some of the files you would typically find in these directories and briefly describe what they do? - In a Linux system, what is the purpose of
/usr/bin? What kind of files are typically stored in this directory and why? - Can you explain the difference between character and block device drivers in UNIX? Can the
lscommand be used to determine whether a device file represents a character device or a block device? If so, how? - How do the directories
/etc,/usr/bin,/var/log, and/optdiffer, and why is it important to understand their distinct roles? - By looking at the contents of
/proc/cpuinfo, can you determine the model of your CPU? What command would you use to display this file's contents? - What hidden files might you expect to find in the
/rootdirectory? Why might these files be hidden? - What command can you use to create a new file system in Linux? What options does this command typically have, and how are they used? Additionally, explain how you would check disk information and partitions on a device, and describe the steps and commands needed to mount the newly created file system.