Filters and Algorithms
VTK’s filters and algorithms allow you to convert your data from “a static dataset” to a dynamic pipeline: you generate something, clean it up, extract meaning, and reshape it into a form that’s easier to analyze or visualize. Think of it like a workshop line: raw material comes in, tools operate on it, and what comes out is clearer, lighter, or more informative.
In real VTK projects you rarely render raw input directly. You almost always process it first: remove noise, compute derived quantities, simplify meshes, extract surfaces, reorganize time steps, or convert data into a representation that downstream steps can handle. Filters are the verbs of VTK. They’re how you do things to data.
One of the major components of VTK is its extensive range of filters and algorithms, designed to process, manipulate, and generate data objects. The important part is not memorizing names, but recognizing what kind of change a filter is making and what assumptions it relies on.
An algorithm is basically anything that runs in the pipeline and does work when you call Update(). A filter is just a very specific kind of algorithm: one that takes data in, changes it, and hands data back out. So vtkSphereSource is an algorithm but not a filter because it doesn’t transform anything, there’s no input, it just generates geometry from scratch. vtkPolyDataMapper is also an algorithm but not a filter because it consumes data and turns it into rendering instructions instead of producing new data for the pipeline. We will demonstrate below a custom DistanceToPointFilter, which on the other hand, is a filter because it sits in the middle, takes polydata, computes something new (distances), and outputs modified polydata. The useful gut check is: if you can logically put it between two other pipeline stages and say “this step modifies the data,” it’s a filter; if it creates data or consumes it for rendering, it’s an algorithm but not a filter.
Everything in the pipeline ultimately derives from vtkAlgorithm. That’s the common base class. If something has SetInputConnection, GetOutputPort, participates in Update(), and runs RequestData, it’s coming from vtkAlgorithm.
There is no single class called “vtkFilter” in the sense people often expect. Instead, filters are defined by behavior, not by one named base class. In practice, most filters inherit from a more specific algorithm subclass that matches the data they operate on:
vtkPolyDataAlgorithm→ filters that take and producevtkPolyDatavtkImageAlgorithm→ image/volume filtersvtkUnstructuredGridAlgorithm, etc.
Purpose and functionality
Filters and algorithms are primarily used for:
- processing and manipulating existing data objects
- generating new datasets (e.g., contours, glyphs, resampled volumes)
- extracting features (regions, surfaces, edges, connected components)
- transforming data into a more useful format (triangles instead of polygons, cleaned points, computed attributes)
A practical habit is to ask: is this step changing geometry, topology, attributes, or time?
- When only the spatial coordinates are adjusted, geometry is affected because point positions move while cells continue to reference the same points, whereas omitting this type of operation leaves shapes unchanged; for example, a shrink or transform filter relocates vertices but keeps the original mesh connectivity intact.
- In cases where the structure of the mesh itself must change, topology is involved because connections between points are altered, while skipping such processing preserves the original cell relationships; for instance, a clipping or triangulation filter can split cells and introduce new triangles that did not previously exist.
- When derived data values are needed for analysis or visualization, modifying attributes is useful because new arrays are computed or existing scalars, vectors, or tensors are updated, whereas leaving attributes untouched limits what can be colored or analyzed; for example, computing normals or gradients adds vectors that can drive lighting or glyphs.
- For datasets that evolve over time, handling time explicitly is beneficial because multiple timesteps can be interpolated, shifted, or summarized, while ignoring time reduces the data to a single static snapshot; for example, a temporal averaging filter can condense many simulation steps into one representative result.
That single question helps you predict what will break later, or why something that “should be the same shape” suddenly behaves differently.
Interaction with data connectivity
A significant part of many operations involves altering or depending on the dataset’s connectivity.
Connectivity refers to relationships inside the data structure: which points belong to which cells, how cells touch, and what “togetherness” means for the dataset. It’s the difference between “points in space” and “a surface,” “a volume,” or “a meaningful region.”
Two datasets can have the same coordinates and still behave differently if connectivity differs. That’s why filters can feel so powerful: they’re not just moving numbers around, they’re preserving or rewriting the relationships that make the data interpretable.
A practical way to phrase it:
- Some filters mainly move coordinates and assume the wiring stays meaningful.
- Other filters explicitly rewrite the wiring.
- Many filters do both, but one of those effects is usually the “main point.”
Understanding connectivity
Connectivity is one of those ideas that seems obvious right until it bites you. If you’ve ever smoothed a mesh and wondered why sharp features disappeared, triangulated polygons and got unexpected results, or extracted a region and got too many pieces, you’ve already seen connectivity in action.
In vtkPolyData, this is especially important because cells (polygons/triangles/lines) don’t store coordinates directly. They store point ids into a shared Points array. That means there’s a difference between:
- Sharing coordinates (two points happen to be in the same place)
- Sharing point ids (two cells literally reference the same point in the points array)
Only the second one is “connected” in the topological sense.
Examples:
- Individual data points without any connectivity:
* * * *- Points connected in a simple linear fashion:
*---*---*---*- Points connected to form a polygon:
polygon:
    *---*
   /     \
  *       *
   \     /
    *---*
And here’s the same idea visually (points + edges + faces as “glue”):
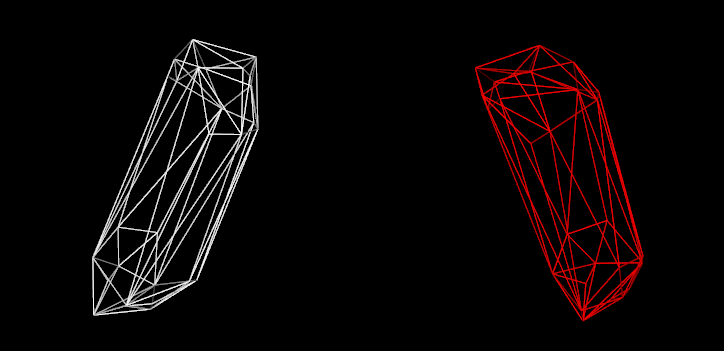
A common real-world pitfall: “looks connected” vs “is connected”
Many meshes coming from certain file formats or pipelines duplicate vertices per face (each polygon has its own private set of points). Visually it can still look like a single surface because the duplicated points have identical coordinates. But topologically it’s a set of separate faces.
This shows up immediately with filters that act per-cell (or per-face), especially shrink-like operations. You shrink each polygon toward its own center and suddenly the mesh “explodes” into detached tiles. The filter isn’t being random; it’s revealing the true connectivity.
Data flow
VTK’s pipeline is intentionally predictable: sources produce data, filters transform it, and outputs feed into the next step. That predictability is what makes large visualization workflows manageable. You can swap filters in and out without rewriting everything because the interfaces and execution model are consistent.
It also makes debugging more systematic. When something looks wrong, the best approach is usually to inspect the pipeline stage-by-stage and find where geometry, topology, or attributes changed in a way you didn’t expect.
The flow typically looks like this:
- Source → Data object → Filter → Data object → (more filters) → Mapper/Renderer
  Input(s)          Filter         Output(s)
+-------------+   +-----------+   +-------------+
| vtkDataSet  |-->| vtkFilter |-->| vtkDataSet  |
+-------------+   +-----------+   +-------------+
A small, practical note: when you’re not inside an active render loop, Update() is what forces a pipeline stage to execute. When you’re “just testing,” it’s very easy to forget Update() and accidentally inspect stale data.
vtkAlgorithm
vtkAlgorithm is the standard interface that makes the pipeline work. If something is a vtkAlgorithm, it plays nicely in VTK: it has input ports, output ports, and can be connected into pipelines without special casing.
A practical way to think about it:
- Sources start the pipeline (create or read data).
- Filters reshape/compute/convert data.
- (Downstream consumers) like mappers and writers consume outputs.
If you’re building VTK programs in C++ or Python, you’ll constantly see this pattern:
- connect algorithms through ports (
SetInputConnection) - adjust parameters
- trigger execution (
Update()or rendering)
Subclasses and roles
- Source algorithms (e.g.,
vtkSphereSource,vtkConeSource) generate or read data objects. - Filter algorithms (e.g.,
vtkShrinkFilter,vtkSmoothPolyDataFilter) process and transform data.
The base class and its conventions are what let you create long, readable pipelines instead of one-off transformations.
Sources
Sources are where your story begins: they generate data (procedural geometry) or read it from files. The reason sources matter isn’t just that they provide input; they define the initial structure, including connectivity, and that structure influences everything downstream.
Examples of sources include:
- Procedural generators:
vtkSphereSource,vtkConeSource - Readers:
vtkSTLReader,vtkXMLPolyDataReader
For instance, vtkSphereSource produces vtkPolyData whose faces share points along edges. That means it’s already a welded surface. Many filters behave “cleanly” on it because the topology is consistent.
Geometric filters
Geometric filters are the “shape editors.” They change point coordinates (move, rotate, smooth, shrink, warp) while often preserving the existing connectivity graph.
This is the category you reach for when you want the same object but with different geometry: less noise, a different scale, a smoother surface, or a transformed pose.
Examples include:
vtkShrinkFilter(shrinks cells inward)vtkSmoothPolyDataFilter(adjusts point positions to smooth a surface)vtkTransformPolyDataFilter(applies a general transform)vtkDecimatePro(often treated as simplification; it reduces triangles and therefore can affect topology too, this one sits on the boundary between “geometric” and “topological” in effect)
Even when connectivity is preserved, geometry changes still affect derived quantities such as normals, curvature, and measurements. That’s why geometric filters aren’t merely cosmetic.
Topological filters
Topological filters are the “rewire the structure” tools. Instead of moving points, they change how points are connected, or generate entirely new cells from existing data.
This matters because topology changes are a different kind of decision: you’re producing a derived representation. That’s often exactly what you want (triangles for rendering, contours for analysis), but it means downstream steps will see a new connectivity structure.
Examples include:
vtkTriangleFilter(converts polygons to triangles)vtkDelaunay2D(constructs 2D Delaunay triangulation, creating new connectivity)vtkContourFilter(generates contours/isosurfaces, producing new geometry and new connectivity)
A normal sign that a topological filter did its job is that counts change: number of points, number of cells, cell types, or the number of connected components.
Scalars and attribute filters in VTK
Attribute filters make your data “smarter.” They add meaning by computing new arrays: gradients, curvature, magnitudes, and other derived quantities. This is where visualization turns into analysis: you’re not just looking at shape, you’re looking at computed properties of the shape.
Examples include:
vtkGradientFilter(adds a vector field representing gradient)vtkVectorNorm(computes vector magnitude as a scalar)vtkCurvatures(computes Gaussian/mean curvature scalars)
One detail that comes up constantly: attributes can live on points or on cells.
- Point data tends to interpolate smoothly across a surface.
- Cell data tends to look piecewise-constant (each polygon has a single value).
If a filter outputs cell data but your mapper expects point data (or vice versa), the visualization can look wrong even though the numbers are fine.
Temporal filters in VTK
Temporal filters exist because time series data has its own problems: timesteps may have changing values, changing attributes, and sometimes changing geometry. Temporal filters help interpolate, normalize, or compute statistics across time without reinventing that logic manually.
Examples include:
vtkTemporalInterpolator(interpolates between timesteps)vtkTemporalShiftScale(shifts and scales time values)vtkTemporalStatistics(computes statistics over time, producing new attributes)
Example: Custom Distance Scalar Filter
This example matches the repo’s example.py and shows a full pipeline with a custom attribute filter. A sphere source feeds a Python-defined filter that computes a per-point distance to a target point and stores it as a scalar array. Those scalars then drive coloring in the mapper.
In Python, the safest base class for a custom VTK filter is VTKPythonAlgorithmBase. It ensures RequestData is actually called, and it exposes a consistent API for input/output ports.
from vtkmodules.util.vtkAlgorithm import VTKPythonAlgorithmBase

class DistanceToPointFilter(VTKPythonAlgorithmBase):
    def __init__(self):
        super().__init__(
            nInputPorts=1,
            nOutputPorts=1,
            inputType="vtkPolyData",
            outputType="vtkPolyData",
        )
        self.TargetPoint = (0.0, 0.0, 0.0)

    def RequestData(self, request, inInfo, outInfo):
        input_data = vtk.vtkPolyData.GetData(inInfo[0])
        output_data = vtk.vtkPolyData.GetData(outInfo, 0)
        output_data.ShallowCopy(input_data)

        distances = vtk.vtkFloatArray()
        distances.SetName("DistanceToTarget")
        distances.SetNumberOfComponents(1)
        distances.SetNumberOfTuples(input_data.GetNumberOfPoints())

        tx, ty, tz = self.TargetPoint
        for i in range(input_data.GetNumberOfPoints()):
            x, y, z = input_data.GetPoint(i)
            distances.SetValue(i, ((x - tx)**2 + (y - ty)**2 + (z - tz)**2) ** 0.5)

        point_data = output_data.GetPointData()
        point_data.AddArray(distances)
        point_data.SetActiveScalars("DistanceToTarget")
return 1- Attributes are attached to point data (
AddArray) and marked active (SetActiveScalars) so the mapper can color by them. - In Python, fetch the filter output with
GetOutputDataObject(0)when you need the scalar range. - The rendered scene uses two independent viewports: the original sphere on the left and the distance-colored sphere on the right, each with its own label. This makes comparison immediate without altering the underlying geometry.
Why “Shrink” Can Break a Mesh
If you want to apply "shrink" filter on your mesh, you probably expect the whole object to scale inward smoothly, like a rubber model getting smaller. In VTK there’s a filter called vtkShrinkPolyData that sounds like it should do exactly that, but it behaves differently: it shrinks each polygon (cell) independently. This is great for inspecting cell structure, but it’s not a global scale.
What the filter actually does is take every cell in the mesh and move that cell’s corner points toward that cell’s own center. The result is a set of smaller, detached copies of the original faces. Because each face is handled independently, shared edges and points are no longer shared in position, so the surface opens up and gaps appear between neighboring faces. The mesh looks “broken,” even though the data is still valid.
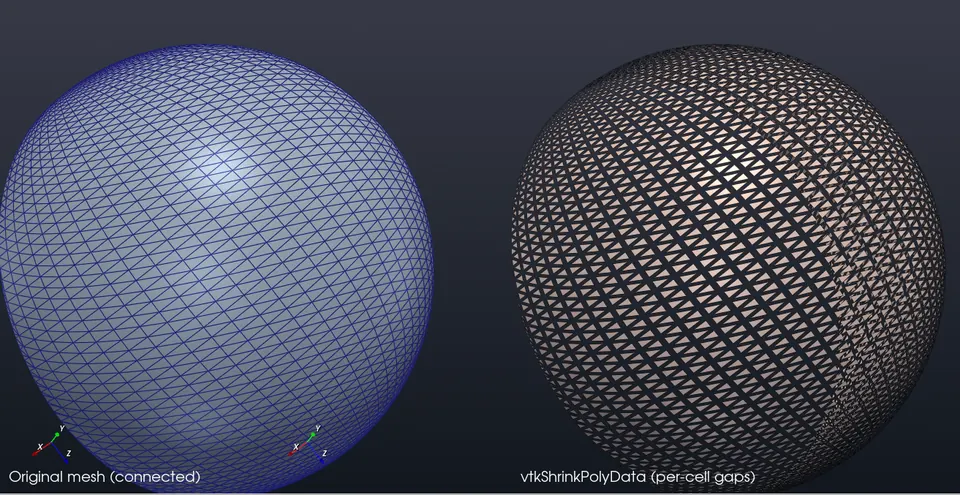
This pitfall is common because per‑cell operations are easy to implement and useful for debugging or visualizing topology. But if the goal is a “connected shrink” effect, where the object stays intact, you need a single global transform applied to the shared points, not per‑cell shrinking. That’s why global scaling about a chosen center (centroid or bounds center) is the go‑to solution for shrinking a mesh without visible cracks.
A practical “connected shrink” alternative (C++)
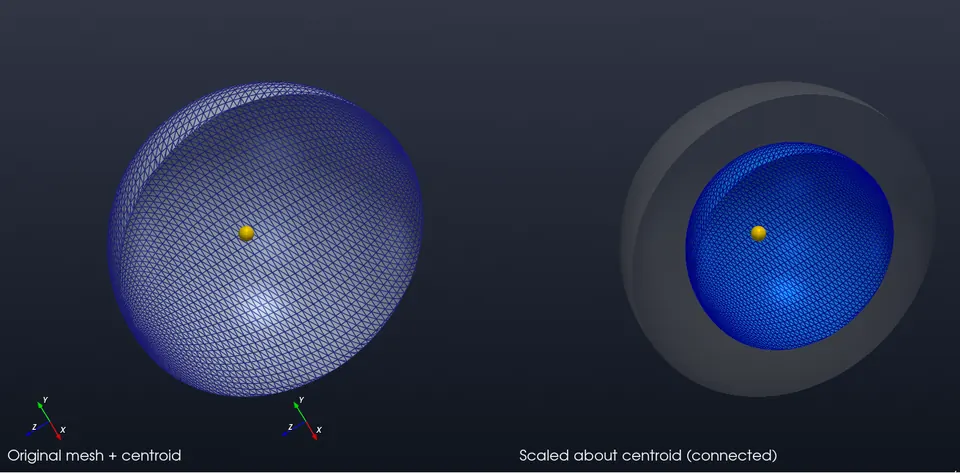
If your goal is “make the whole mesh smaller toward its center” without breaking it into detached faces, a global transform is usually the cleanest solution. Unlike vtkShrinkPolyData / vtkShrinkFilter (which act per-cell), a transform acts on points. If your mesh is connected (adjacent cells share point ids), moving points with a single global transform keeps the surface connected automatically.
The idea is simple:
- choose a center (mesh centroid or bounding-box center)
- translate so that center is at the origin
- scale
- translate back
That’s it. You’re scaling the entire object as one piece.
Option A: Scale about the centroid (good “physical” center)
The centroid here is computed from the mesh’s points (optionally weighted). This often feels like “shrink toward the mass center” and is a good default for irregular shapes.
#include <vtkSmartPointer.h>
#include <vtkPolyData.h>
#include <vtkCenterOfMass.h>
#include <vtkTransform.h>
#include <vtkTransformPolyDataFilter.h>

// Scales a vtkPolyData uniformly about its centroid.
// scale < 1.0 shrinks, scale > 1.0 grows.
vtkSmartPointer<vtkPolyData> ScalePolyDataAboutCentroid(vtkPolyData* input, double scale)
{
    if (!input)
        return nullptr;

    // 1) Compute centroid (center of mass) from points.
    auto com = vtkSmartPointer<vtkCenterOfMass>::New();
    com->SetInputData(input);
    com->SetUseScalarsAsWeights(false); // set true if you want scalar-weighted centroid
    com->Update();

    double c[3];
    com->GetCenter(c);

    // 2) Build transform: T(c) * S(scale) * T(-c)
    auto transform = vtkSmartPointer<vtkTransform>::New();
    transform->PostMultiply();                 // apply in the order we add them
    transform->Translate(c[0], c[1], c[2]);
    transform->Scale(scale, scale, scale);
    transform->Translate(-c[0], -c[1], -c[2]);

    // 3) Apply transform to the polydata
    auto tfilter = vtkSmartPointer<vtkTransformPolyDataFilter>::New();
    tfilter->SetInputData(input);
    tfilter->SetTransform(transform);
    tfilter->Update();

    return tfilter->GetOutput();
}
What this does
- Every point in the mesh is scaled relative to the same center.
- Connectivity is preserved because cells still reference the same point ids, only point coordinates change.
- You get a “connected shrink” effect even when per-cell shrink would create gaps.
When centroid is a good choice
- organic or irregular shapes
- meshes where “visual center” should track the distribution of points
Option B: Scale about the bounding-box center (fast, predictable)
Sometimes you want the center of the mesh’s bounds (midpoint of min/max in x/y/z). This is simpler and doesn’t require computing a centroid, and it matches what many people expect as a “visual center” for symmetric objects.
#include <vtkSmartPointer.h>
#include <vtkPolyData.h>
#include <vtkPoints.h>
#include <vtkTransform.h>
#include <vtkTransformPolyDataFilter.h>

vtkSmartPointer<vtkPolyData> ScalePolyDataAboutBoundsCenter(vtkPolyData* input, double scale)
{
    if (!input)
        return nullptr;

    double bounds[6];
    input->GetBounds(bounds);

    const double cx = 0.5 * (bounds[0] + bounds[1]);
    const double cy = 0.5 * (bounds[2] + bounds[3]);
    const double cz = 0.5 * (bounds[4] + bounds[5]);

    auto transform = vtkSmartPointer<vtkTransform>::New();
    transform->PostMultiply();
    transform->Translate(cx, cy, cz);
    transform->Scale(scale, scale, scale);
    transform->Translate(-cx, -cy, -cz);

    auto tfilter = vtkSmartPointer<vtkTransformPolyDataFilter>::New();
    tfilter->SetInputData(input);
    tfilter->SetTransform(transform);
    tfilter->Update();

    return tfilter->GetOutput();
}
When bounds center is a good choice
- symmetric objects (CAD-like)
- when you want behavior that’s stable even if point distribution is uneven
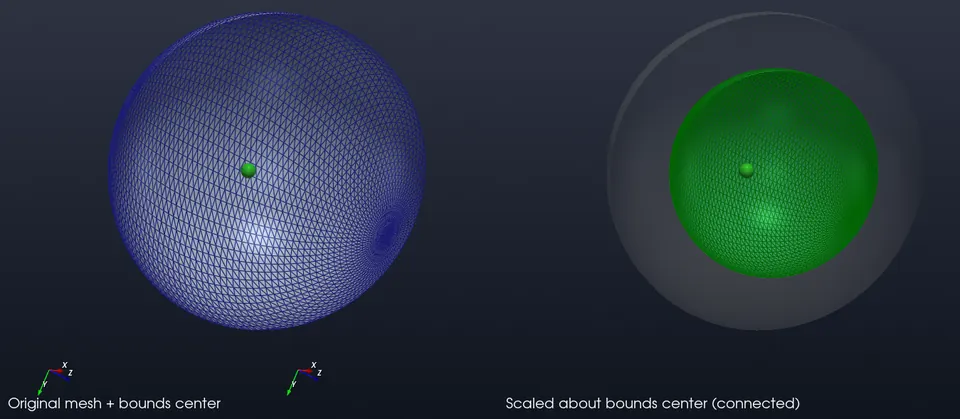
Why this preserves connectivity (and shrink filters may not)?
A vtkPolyData surface stays connected when adjacent polygons share the same point ids. A global transform modifies point coordinates in the Points array, but it does not change which points each cell references. So adjacency remains intact.
By contrast, cell-based shrink filters conceptually pull each cell toward its own center. If your mesh isn’t welded (each polygon has its own duplicate vertices), cells don’t share points, so they shrink independently and gaps appear.
- When adjusting the amount of shrink visually, choosing a scale factor such as 0.95, 0.8, or 0.5 is helpful because the geometry becomes progressively smaller in a controlled way, whereas omitting this choice or using extreme values like 0.0 can collapse cells into unusable shapes; for example, a factor of 0.8 is often used in mesh inspection to clearly separate cells without destroying their overall form.
- In scenes that rely on lighting for depth perception, recomputing surface normals after shrinking is useful because lighting will correctly reflect the updated geometry, while skipping this step can result in flat or incorrect shading; for instance, applying
vtkPolyDataNormalsafter shrinking a model ensures a rendered sphere still appears smoothly lit instead of patchy. - If different amounts of shrink are desired along different axes, applying anisotropic scaling through separate x, y, and z scale values can be beneficial for controlled deformation, whereas omitting this option limits you to uniform changes that preserve proportions; for example, scaling more along the z-axis than x and y can intentionally flatten a sphere into an oblate shape for visualization experiments.
This transform approach is a good “first choice” when the mental model is “shrink the object” rather than “shrink each face.”
Summary
This is a quick reference, but the more important takeaway is what each category means:
- Sources ingest and initialize datasets from external inputs or generators.
- Geometric filters perform transformations on spatial representations, modifying coordinate positions or shapes while preserving connectivity.
- Topological filters alter the connectivity or structural relationships between elements, rewriting the underlying graph or mesh structure.
- Attribute filters compute, derive, or transform metadata fields, enriching elements with additional semantic or quantitative properties.
- Temporal filters process data across multiple timesteps, enabling time-based aggregation, interpolation, or evolution analysis.
| Category | Class Name | Description |
|---|---|---|
| Sources | vtkSphereSource | Generates spherical polydata. |
| vtkConeSource | Creates conical polydata. | |
| vtkSTLReader | Reads STL files. | |
| vtkXMLPolyDataReader | Reads VTK’s XML polydata files. | |
| Geometric Filters | vtkShrinkFilter | Shrinks cells inward (appearance depends on connectivity). |
| vtkSmoothPolyDataFilter | Smooths polydata by adjusting point positions. | |
| vtkDecimatePro | Reduces triangle count (often affects topology). | |
| Topological Filters | vtkTriangleFilter | Converts polygons to triangles. |
| vtkDelaunay2D | Constructs a 2D Delaunay triangulation. | |
| vtkContourFilter | Generates contours/isosurfaces from scalar fields. | |
| Scalars & Attribute Filters | vtkGradientFilter | Computes gradient of a scalar field (adds vector attribute). |
| vtkVectorNorm | Computes magnitude of vector data (adds scalar attribute). | |
| vtkCurvatures | Computes curvature measures (adds scalar attributes). | |
| Temporal Filters | vtkTemporalInterpolator | Interpolates data between time steps. |
| vtkTemporalShiftScale | Shifts and scales time values. | |
| vtkTemporalStatistics | Computes statistics over time (adds attributes). | |
| Other | vtkAlgorithm | Base pipeline interface for algorithms (ports + execution model). |