Introduction to Machine Learning
Machine Learning (ML), a subset of artificial intelligence, is the scientific study of algorithms and statistical models that computer systems use to effectively perform a specific task without using explicit instructions. It relies on patterns and inference instead. ML algorithms build a mathematical model based on sample data, known as "training data," to make predictions or decisions without being explicitly programmed to perform the task.
Types of Machine Learning
- Supervised learning involves the use of labeled training data to infer a function that maps input data to the corresponding output. The goal is to learn from example input-output pairs to make accurate predictions on new data.
- In unsupervised learning, the algorithm is designed to learn from plain data without any corresponding output variables to guide the learning process. This type of learning aims to identify patterns, relationships, or structures within the data.
- Reinforcement learning focuses on training algorithms that learn optimal actions through trial and error. This learning method is concerned with how software agents should take actions in an environment to maximize a notion of cumulative reward.
Deep Learning in Machine Learning
Deep learning uses multiple learned transformations to build representations of inputs. A layer can combine edges into shapes or local patterns into broader features, depending on its architecture and training objective. This is a mathematical model of a task rather than a literal simulation of human reasoning. Two important architectures are:
- Convolutional Neural Networks (CNNs) are used primarily for processing data with a grid-like topology, such as images.
- Recurrent Neural Networks (RNNs) are suitable for processing sequential data, such as time series or text.
Applications and Suitability
Deep learning is particularly useful in areas such as image and speech recognition, where the volume and complexity of data surpass the capabilities of traditional algorithms.
Prevalence of Machine Learning
Learning is useful when representative examples are easier to obtain than a complete set of decision rules. Its usefulness depends on the quality of those examples, the information available at prediction time, and a measurable objective. More data from a biased or outdated collection process can reinforce the wrong relationship.
Practical Applications of Machine Learning
- Database Mining is utilized in areas like internet search, understanding user behavior, medical diagnosis, and genomics.
- Autonomous Systems include self-driving cars, drones, and other systems that make decisions based on data.
- Recognition Tasks encompass handwriting, speech, and facial recognition.
- Natural Language Processing enables machines to understand and respond to human language.
- Self-Customizing Programs are used in personalized recommendation systems like those on Netflix, Amazon, and iTunes.
Foundational Concepts and Definitions
- Arthur Samuel (1959) defined machine learning as a field of study that enables computers to learn without being explicitly programmed. His pioneering work laid the foundation for the development of algorithms that allow computers to improve their performance on tasks through experience rather than through direct programming.
- Tom Mitchell (1997) proposed a formal definition of machine learning. According to him, a computer program is said to learn from experience E concerning task T and performance measure P if its performance on T, as measured by P, improves with experience E. This definition emphasizes the importance of measurable improvement in performance as a result of experience, framing machine learning as a process that benefits from data-driven feedback and iterative enhancement.
Supervised Learning
Supervised learning, a dominant approach in machine learning, focuses on using labeled datasets to train algorithms. The fitted model is then evaluated on new examples to determine how accurately it predicts; supervised training alone does not guarantee that accuracy.
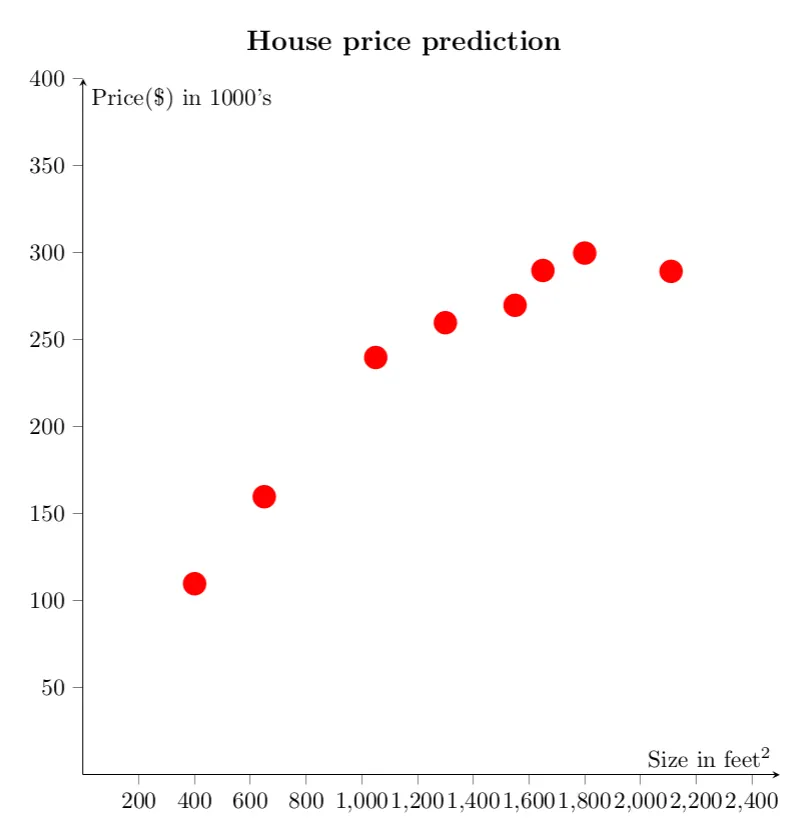
House Price Prediction - Regression Example
Consider a typical problem: predicting house prices based on their size. For instance, estimating the price of a 750 square feet house. This problem can be approached using different models:
- Linear Regression involves using a straight line to fit the data, modeling the relationship between the dependent and independent variables.
- Polynomial Regression entails fitting a curved line, such as a second-order polynomial, to better capture the complexity of the relationship between variables.
Tumor Size and Prognosis - Classification Example
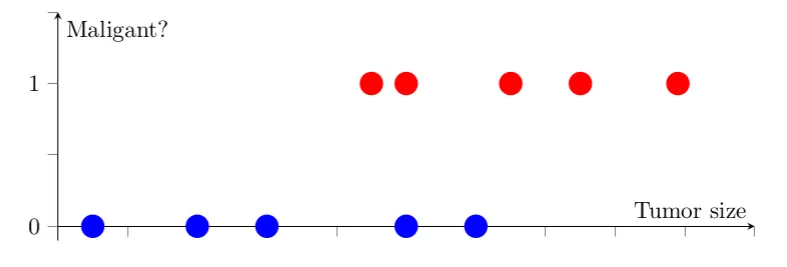
In a classification problem, the aim is to categorize data into discrete groups. For example, determining if a tumor is malignant based on its size is a classic classification problem.
Combining Multiple Attributes
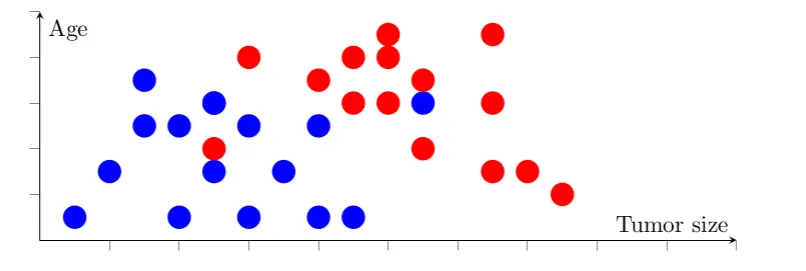
When considering multiple attributes, such as age and tumor size, classification becomes more intricate. We can use algorithms to draw boundaries between different classes in this multidimensional feature space.
Unsupervised Learning
Unsupervised learning, in contrast to supervised learning, uses datasets without predefined labels. The goal here is to identify patterns or structures within the data.
Clustering Algorithm Examples
- Google News clusters similar news stories to provide users with grouped articles on the same topic.
- Genomics involves classifying types of genetic expressions to understand genetic differences and similarities.
- Microarray Data is used for grouping individuals based on gene expression patterns to study variations in gene activity.
- Computer Clusters organize clusters to optimize performance or identify faults, improving computational efficiency.
- Social Network Analysis analyzes customer data in social networks to understand relationships and interactions.
- Astronomical Data classifies celestial objects based on their properties to facilitate the study of the universe.
The Cocktail Party Problem
The Cocktail Party Problem is an audio processing challenge where the goal is to separate individual audio sources from a mixture of sounds. This scenario is common in environments like parties, where multiple people are talking simultaneously, and you want to isolate the speech of a single person from a recording that captures all the speakers.
- The objective in the Cocktail Party Problem is to extract distinct audio signals from a complex mixture. This mixture can be influenced by factors such as room acoustics and overlapping speech, making it a challenging task.
- A common approach to solve this problem is Blind Source Separation (BSS). The goal of BSS is to recover original audio signals (the sources) from mixed signals without knowledge about the mixing process.
- Singular Value Decomposition (SVD) can support preprocessing or compression, but does not by itself identify the original sources. SVD decomposes a matrix, representing audio data, into three matrices that expose the fundamental structure of the data. The mathematical representation of SVD applied to a matrix $X$ (representing mixed audio signals) is:
$$ X = U \Sigma V^* $$
Where:
- $X$ is the matrix of mixed signals.
- $U$ and $V$ are orthogonal matrices.
- $S$ is a diagonal matrix with singular values.
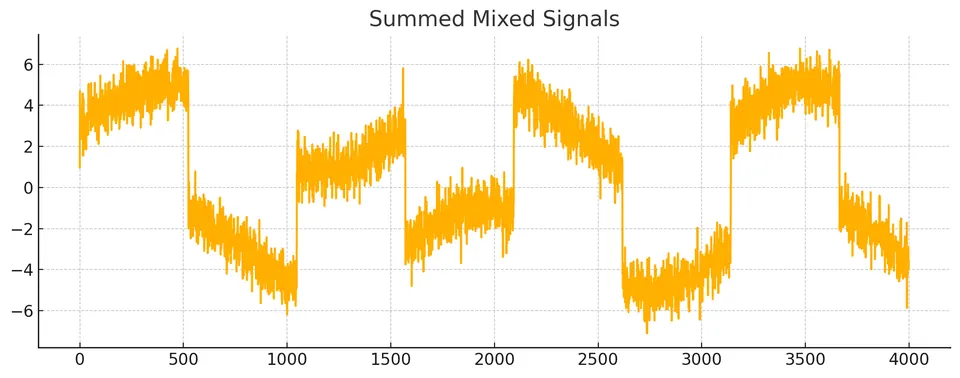
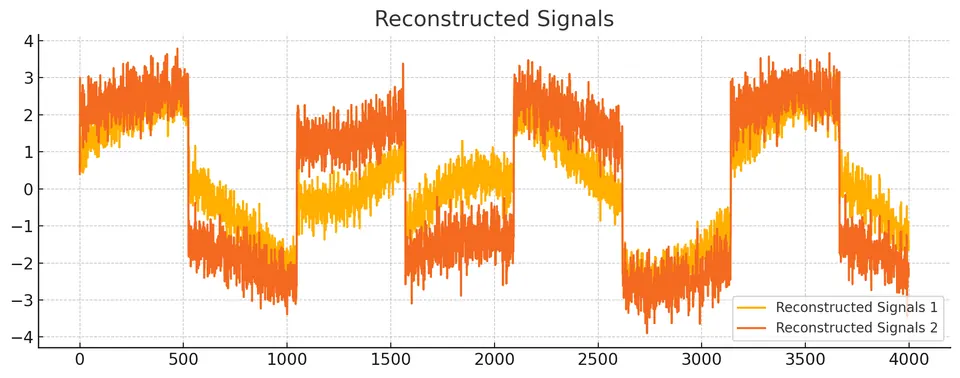
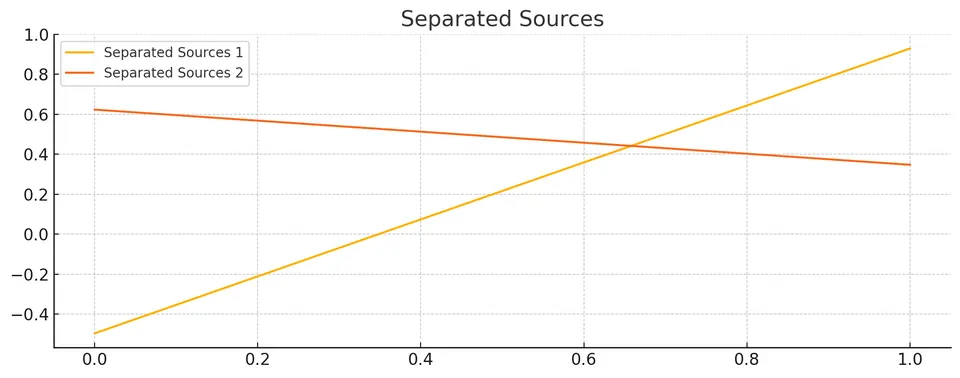
For two recorded channels, retaining both nonzero singular values reconstructs the recorded mixtures. It changes neither their information nor their source identity. Retaining fewer components can discard information, and decorrelating components is weaker than making them independent. ICA adds assumptions about independent source distributions to identify a mixing transformation, generally up to sign, scale, and permutation. The synthetic example compares known generated sources with recovered components; a convincing match requires checking their waveforms or correlations after accounting for those ambiguities.
The following executable simulation reconstructs the two recorded channels with SVD and applies ICA to the resulting sample-by-channel matrix. Each row is a time sample; each column is a channel. The plotting functions receive transposed arrays only for drawing separate curves:
import numpy as np
import matplotlib.pyplot as plt
from sklearn.decomposition import FastICA

# Function to perform Singular Value Decomposition
def perform_svd(X):
    U, S, V = np.linalg.svd(X, full_matrices=False)
    return U, S, V

# Function to plot individual signals
def plot_individual_signals(signals, title):
    plt.figure(figsize=(10, 4))
    for i, signal in enumerate(signals):
        plt.plot(signal, label=f'{title} {i+1}')
    plt.title(title)
    plt.legend()
    plt.tight_layout()
    plt.show()

# Function to plot a single signal
def plot_single_signal(signal, title):
    plt.figure(figsize=(10, 4))
    plt.plot(signal)
    plt.title(title)
    plt.tight_layout()
    plt.show()

# Generate original signals for comparison
def generate_original_signals():
    np.random.seed(0)
    time = np.linspace(0, 8, 4000)
    s1 = np.sin(2 * time)  # Signal 1 : sinusoidal signal
    s2 = np.sign(np.sin(3 * time))  # Signal 2 : square signal
    return np.c_[s1, s2]

# Generate mixed signals for demonstration purposes
def simulate_mixed_signals():
    S = generate_original_signals()
    S += 0.2 * np.random.normal(size=S.shape)  # Add noise
    S /= S.std(axis=0)  # Standardize data

    # Mixing matrix
    A = np.array([[1, 1], [0.5, 2]])
    X = np.dot(S, A.T)  # Generate observations
    return X, S  # Return both mixed signals and original sources

# Generate mixed and original signals
mixed_signals, original_sources = simulate_mixed_signals()

# Perform SVD on the mixed signals
U, S, V = perform_svd(mixed_signals)

# Reconstruct the signals using the top singular values
top_k = 2  # Number of top components to use for reconstruction
reconstructed = np.dot(U[:, :top_k], np.dot(np.diag(S[:top_k]), V[:top_k, :]))

# Apply Independent Component Analysis (ICA) to separate the sources
ica = FastICA(n_components=2, random_state=0, whiten="unit-variance")
sources = ica.fit_transform(reconstructed)
assert sources.shape == original_sources.shape
np.testing.assert_allclose(reconstructed, mixed_signals, atol=1e-10)

# Sum the mixed signals to represent the original combined signal
summed_mixed_signals = mixed_signals.sum(axis=1)

# Plot the summed mixed signals, reconstructed signals, and separated sources
plot_single_signal(summed_mixed_signals, 'Summed Mixed Signals')
plot_individual_signals(reconstructed.T, 'Reconstructed Signals')
plot_individual_signals(sources.T, 'Separated Sources')
Original signal:
Reconstructed signals:
Separated sources:
Define the Task before Choosing an Algorithm
A supervised problem needs a prediction unit, inputs available for that unit, a target, and a loss. For house pricing, a row might represent one sale, the inputs might be size and location recorded before the sale, and the target might be its sale price. Including a fee calculated from the final sale price would expose information that the intended predictor would not have.
Regression and classification describe target types, rather than a guarantee about an algorithm's behavior. Linear regression estimates a real-valued response. Logistic regression estimates a conditional class probability, which a threshold can turn into a discrete decision. A cluster label instead summarizes an arrangement of inputs; it is not automatically a ground-truth category.
The empirical training objective averages losses over the training sample:
$$ \hat R(\theta)=\frac1m\sum_{i=1}^m \ell(h_\theta(x^{(i)}),y^{(i)}). $$
The deployment objective averages losses over the population where the predictor will be used. Those averages can differ because of sampling variation, model selection, or a changed population. A train/test split estimates useful performance only when its units and available information represent that deployment problem.
Worked Calculation: Compare a Learned Rule with a Baseline
Use training inputs $0,1,2,3$ with targets $1,3,5,7$. These points follow $y=1+2x$. The least-squares fitted intercept is one and slope two. At held-out inputs four and five, predictions are nine and eleven.
A baseline that always predicts the training-target mean uses $(1+3+5+7)/4=4$. Its absolute test errors are five and seven, giving mean absolute error six. The learned rule has MAE zero on these constructed targets. This calculation verifies the fitting and evaluation mechanics; two noiseless test points do not establish performance for a real housing market.
import numpy as np
from sklearn.dummy import DummyRegressor
from sklearn.linear_model import LinearRegression
from sklearn.metrics import mean_absolute_error
X_train = np.arange(4.0).reshape(-1, 1)
y_train = np.array([1.0, 3.0, 5.0, 7.0])
X_test = np.array([[4.0], [5.0]])
y_test = np.array([9.0, 11.0])
model = LinearRegression().fit(X_train, y_train)
baseline = DummyRegressor(strategy='mean').fit(X_train, y_train)
prediction = model.predict(X_test)
mae = np.abs(prediction - y_test).mean()
baseline_mae = mean_absolute_error(y_test, baseline.predict(X_test))
np.testing.assert_allclose([model.intercept_, model.coef_[0]], [1.0, 2.0])
np.testing.assert_allclose(mae, mean_absolute_error(y_test, prediction))
np.testing.assert_allclose([mae, baseline_mae], [0.0, 6.0], atol=1e-12)
print('predictions:', prediction, 'MAE:', round(mae, 12))
print('training-mean baseline MAE:', baseline_mae)
The model and baseline are fitted on exactly the same training observations. Neither uses the test targets to set its parameters. A useful comparison must also use the same test units and the same loss. Reporting training fit for one model and test fit for another would answer different questions.
MAE has the target's units, while mean squared error has squared units and emphasizes large errors more strongly. For errors two and eight, MAE is five but MSE is 34. A business or scientific objective determines which behavior is appropriate; the metric should be chosen before inspecting which model wins.
What Unsupervised Structure Establishes
Clustering, compression, and source separation impose different assumptions on the same inputs. K-means seeks compact groups under a chosen distance. PCA seeks directions explaining squared variation. ICA seeks components under an independence model. A successful numerical optimization establishes success for that objective; the usefulness of its structure still needs a substantive interpretation or a downstream evaluation.
In the audio example, a full-rank SVD reconstruction should match the mixtures to numerical precision. That check verifies matrix orientation and reconstruction. It does not verify source separation. ICA components must be compared with the generated sources after allowing their arbitrary order and signs. For real recordings, where the sources are unknown, evaluating recovery requires external information or a task-specific criterion.
The distinction between training success and task success appears throughout machine learning. A small loss can result from a suitable model, an easy constructed example, duplicated observations, or leaked information. An implementation check should isolate arithmetic and shape errors; a separate evaluation should assess the intended task.
Reference
These notes are based on the free video lectures offered by Stanford University, led by Professor Andrew Ng. These lectures are part of the renowned Machine Learning course available on Coursera. For more information and to access the full course, visit the Coursera course page.