Gradient Descent
Gradient descent is a first-order method for minimizing a differentiable objective in mathematics, statistics, machine learning, and artificial intelligence. At the current point, the gradient gives the direction of steepest local increase in the Euclidean norm. The method moves in the opposite direction, using a positive step size to control the distance traveled. Each update therefore combines two decisions: which direction reduces the local linear model, and how far that model can be trusted. Its low cost per iteration makes gradient descent useful when the number of variables is large and second derivatives are expensive.
Because it only requires the gradient of the function rather than its Hessian or other higher-order derivatives, gradient descent is often the method of choice for large-scale optimization problems. For instance, in machine learning, gradient descent is the backbone of training many models, from linear regression to deep neural networks.
Conceptual Illustration:
Imagine the function $f(x)$ as a landscape of hills and valleys. Gradient descent resembles a blindfolded hiker who can feel the slope of the ground beneath their feet. The hiker takes small steps in the direction of the steepest downward slope to eventually reach a valley (a minimum of $f$).
In higher dimensions (e.g., $x \in \mathbb{R}^n$), this idea generalizes similarly, just with gradients represented as vectors.
Mathematical formulation
Given a differentiable function $f : \mathbb{R}^n \to \mathbb{R}$, we want to solve:
$$ \min_{x \in \mathbb{R}^n} f(x) $$
gradient descent Update Rule:
At iteration $k$, we have the current approximation $x_k$. The gradient at $x_k$, denoted $\nabla f(x_k)$, points in the direction of greatest increase of $f$. To move towards a minimum, we take a step opposite to the gradient direction:
$$ x_{k+1} = x_k - \alpha \nabla f(x_k) $$
where $\alpha > 0$ is the learning rate (also called the step size).
Main Components:
- The gradient $\nabla f(x)$ collects the first partial derivatives in a vector. Its inner product with a unit direction gives the directional derivative, and its own direction gives the steepest local increase in the Euclidean norm.
- The learning rate $\alpha$ controls how far the iterate moves along the negative gradient. A large value can overshoot the minimum or cause divergence; a small value may require many iterations. A useful choice depends on the curvature of the objective, as the derivation below makes precise.
Over successive iterations, provided the learning rate is chosen suitably and the function is well-behaved (e.g., convex), $x_k$ converges to a point $x^*$ where $\nabla f(x^*) = 0$, indicating a critical point, often a minimum.
Derivation
Step 1: First-order Taylor expansion.
Consider the first-order Taylor expansion of $f$ at $x_k$:
$$ f(x_{k+1}) \approx f(x_k) + \nabla f(x_k)^\top (x_{k+1} - x_k) $$
To reduce $f$, we want $x_{k+1}$ to move in a direction that decreases this linear approximation. The direction that maximally decreases $f$ is the opposite of $\nabla f(x_k)$.
Step 2: Steepest descent.
The direction of steepest descent is given by $-\nabla f(x_k)$. To decide how far to move in that direction, we introduce the learning rate $\alpha$. Thus, the next iterate is:
$$ x_{k+1} = x_k - \alpha \nabla f(x_k) $$
Step 3: Convergence considerations.
For a convex objective with an $L$-Lipschitz gradient and an attained minimum in $\mathbb R^n$, a fixed step $0<\alpha\leq1/L$ gives the usual convergence guarantee to a minimizer. Under these assumptions, the sequence satisfies:
$$ \lim_{k \to \infty} x_k = x^* $$
where $x^*$ is a minimizer of $f$.
Why the step decreases the objective
For a unit vector $d$, the directional derivative is $\nabla f(x)^\top d$. By the Cauchy–Schwarz inequality,
$$ \nabla f(x)^\top d \geq -\|\nabla f(x)\|_2, $$
with equality at $d=-\nabla f(x)/\|\nabla f(x)\|_2$ when the gradient is nonzero. This is the precise meaning of steepest descent in the Euclidean norm; the direction depends on the norm being used.
The linear Taylor model alone does not determine a safe step length. Suppose the gradient is $L$-Lipschitz, meaning $\|\nabla f(x)-\nabla f(y)\|_2\leq L\|x-y\|_2$. The resulting quadratic upper bound gives
$$ f(x-\alpha\nabla f(x))\leq f(x)-\alpha\left(1-\frac{L\alpha}{2}\right)\|\nabla f(x)\|_2^2. $$
Thus $0<\alpha<2/L$ guarantees a decrease whenever the gradient is nonzero. The common choice $\alpha\leq1/L$ gives a convenient margin. Convexity makes a stationary point globally optimal; strong convexity also ensures uniqueness and a linear convergence rate. For a nonconvex function, a small gradient establishes approximate stationarity, which may also occur near a saddle point.
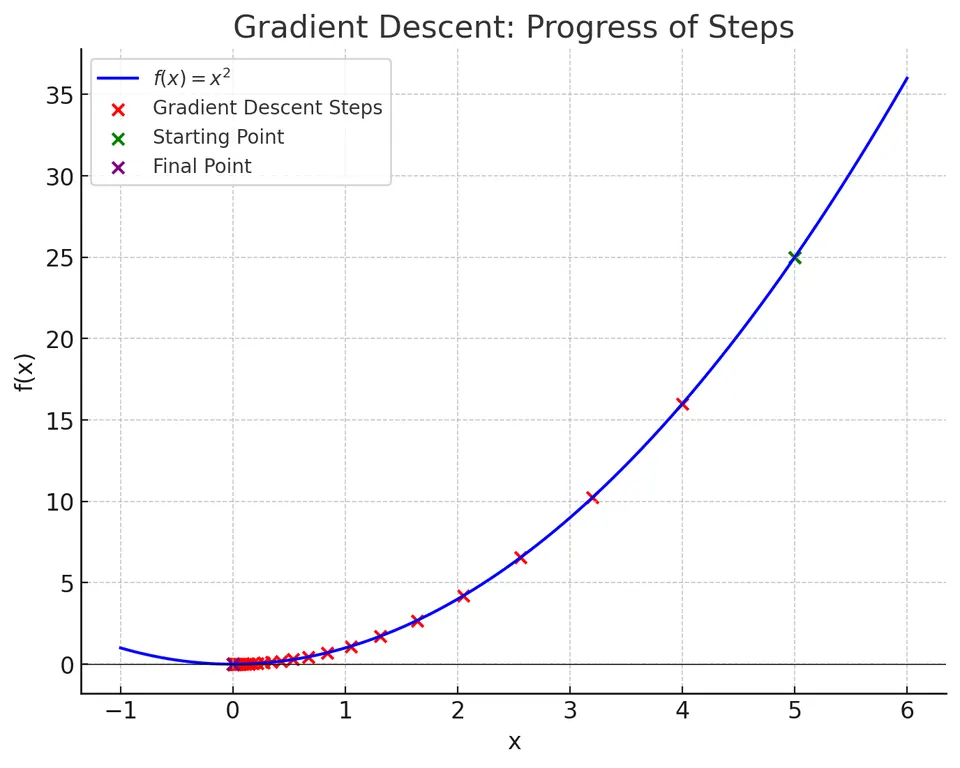
For the example $f(x)=x^2$, the update becomes $x_{k+1}=(1-2\alpha)x_k$, so $x_k=(1-2\alpha)^k x_0$. Convergence requires $|1-2\alpha|<1$, or $0<\alpha<1$. With $\alpha=0.1$, the factor is $0.8$, explaining every value in the worked example.
Algorithm steps
Input:
- A differentiable function $f(x)$.
- A starting point $x_0$.
- A learning rate $\alpha > 0$.
- A convergence tolerance $\epsilon > 0$ or a maximum number of iterations $k_{\max}$.
Initialization:
Set $k = 0$.
Iteration:
Step 1. Compute the gradient at the current point:
$$ g_k = \nabla f(x_k). $$
Step 2. Check for convergence:
- If $\|g_k\| < \epsilon$, stop and return $x_k$.
- If $k \geq k_{\max}$, stop without convergence.
Step 3. Update the point:
$$ x_{k+1} = x_k - \alpha g_k. $$
Step 4. Increment $k = k+1$ and repeat from step I.
Output:
- Approximate minimum $x_k$.
- Number of iterations performed, if tracked as a diagnostic. The repository function
gradient_descentreturns only the approximate point, rather than a point-and-count pair.
Example
Given Function:
$$ f(x) = x^2. $$
We know $f$ is minimized at $x = 0$. Let’s apply gradient descent step-by-step to illustrate how the algorithm converges to $x=0$.
Setup:
- Initial guess: $x_0 = 5$.
- Learning rate: $\alpha = 0.1$.
- Gradient: $f'(x) = 2x$.
Iteration 1:
- Current point: $x_0 = 5$.
- Compute gradient: $f'(5) = 2 \cdot 5 = 10$.
Update:
$$ x_1 = x_0 - \alpha f'(x_0) = 5 - 0.1 \cdot 10 = 5 - 1 = 4. $$
Iteration 2:
- Current point: $x_1 = 4$.
- Compute gradient: $f'(4) = 2 \cdot 4 = 8$.
Update:
$$ x_2 = x_1 - \alpha f'(x_1) = 4 - 0.1 \cdot 8 = 4 - 0.8 = 3.2. $$
Iteration 3:
- Current point: $x_2 = 3.2$.
- Compute gradient: $f'(3.2) = 2 \cdot 3.2 = 6.4$.
Update:
$$ x_3 = x_2 - \alpha f'(x_2) = 3.2 - 0.1 \cdot 6.4 = 3.2 - 0.64 = 2.56. $$
Continuing this process, we observe that $x_k$ keeps getting closer to 0. Over many iterations, the point will approach the exact minimum at $x = 0$.
Advantages
- Simplicity and ease of implementation make gradient descent a popular choice, as it only requires first-order gradients and is straightforward to code.
- Scalability allows gradient descent to handle problems with large parameter spaces, such as deep learning models with millions of parameters, and advanced variants like stochastic gradient descent enhance its applicability in machine learning.
- No need for second-order information makes it computationally cheaper than methods requiring Hessians, as it relies solely on first-order derivatives.
- Versatility enables its application to a wide range of differentiable functions, particularly in complex, high-dimensional optimization problems.
Limitations
- Learning rate sensitivity poses a challenge, as selecting a learning rate $\alpha$ that is too large can cause divergence, while a small $\alpha$ may lead to very slow convergence.
- Local minima and saddle points in non-convex optimization problems can trap gradient descent, preventing it from finding the global minimum or causing it to plateau.
- Ill-conditioned problems with elongated contours or ravines can cause inefficient convergence, often requiring preconditioning or adaptive techniques to address the issue.
- Dependence on good initialization means poor starting points may lead to suboptimal solutions or prolonged convergence, particularly in functions with challenging landscapes.