Jacobi Method
Jacobi iteration approximates the solution of a linear system $A\mathbf x=\mathbf b$ by repeatedly updating every component from the previous iterate. Each row is solved for the variable on its diagonal, with all other components held at their old values during that sweep. The resulting vector becomes the input to the next sweep. This avoids the factorization used by direct methods such as Gaussian elimination and makes the component updates independent within an iteration. Whether the approximations approach the exact solution depends on the coefficient matrix and its splitting; the ability to compute an update alone does not establish convergence.
One of the key characteristics of the Jacobi method is that each component of the solution vector is updated using only values from the previous iteration. This makes the method amenable to parallelization, as each component’s update is independent from the others at a given iteration.
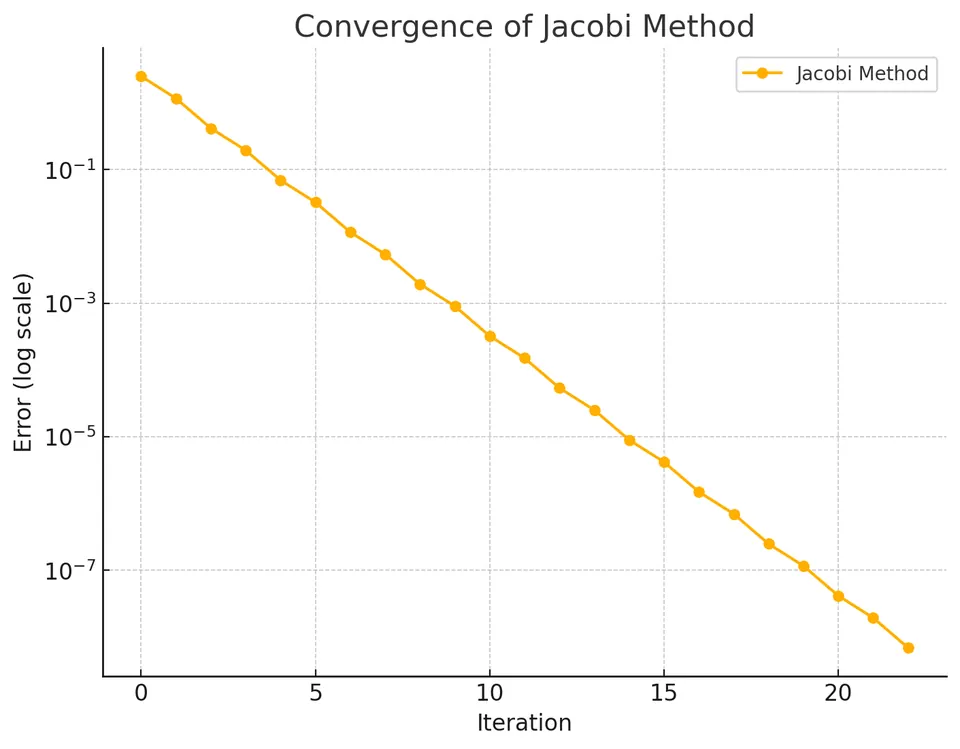
Mathematical formulation
Consider the linear system:
$$ A\mathbf{x} = \mathbf{b}, $$ where
$$ A = \begin{bmatrix} a_{11} & a_{12} & \cdots & a_{1n}\\ a_{21} & a_{22} & \cdots & a_{2n}\\ \vdots & \vdots & \ddots & \vdots\\ a_{n1} & a_{n2} & \cdots & a_{nn} \end{bmatrix} $$
$$ \mathbf{x} = \begin{bmatrix} x_1 \\ x_2 \\ \vdots \\ x_n \end{bmatrix} $$
$$ \mathbf{b} = \begin{bmatrix} b_1 \\ b_2 \\ \vdots \\ b_n \end{bmatrix} $$
If we split $A$ into its diagonal and off-diagonal parts, we have:
$$ A = D + L + U $$
where:
- $D = \text{diag}(a_{11}, a_{22}, \ldots, a_{nn})$ is the diagonal matrix containing the diagonal elements of $A$.
- $L$ is the strictly lower-triangular part of $A$ (all elements below the main diagonal).
- $U$ is the strictly upper-triangular part of $A$ (all elements above the main diagonal).
The system $A\mathbf{x} = \mathbf{b}$ can then be written as:
$$ D\mathbf{x} = \mathbf{b} - (L + U)\mathbf{x}. $$
Solving for $\mathbf{x}$:
$$ \mathbf{x} = D^{-1}(\mathbf{b} - (L + U)\mathbf{x}). $$
The Jacobi iteration proceeds by using the values of $\mathbf{x}$ from the previous iteration on the right-hand side. Let $\mathbf{x}^{(k)}$ denote the approximation of the solution after $k$ iterations. Then the iteration rule is:
$$ \mathbf{x}^{(k+1)} = D^{-1}\bigl(\mathbf{b} - (L + U)\mathbf{x}^{(k)}\bigr). $$
This can be written component-wise as:
$$ x_i^{(k+1)} = \frac{b_i - \sum_{\substack{j=1 \\ j \ne i}}^{n} a_{ij} x_j^{(k)}}{a_{ii}}, \quad \text{for } i = 1, 2, \ldots, n. $$
Derivation
The derivation of the Jacobi method starts from the linear system $A\mathbf{x} = \mathbf{b}$. By isolating each equation’s unknown on its diagonal component, you effectively perform a "fixed-point" iteration. Consider the $i$-th equation:
$$ a_{ii} x_i + \sum_{\substack{j=1 \\ j \ne i}}^{n} a_{ij} x_j = b_i. $$
Rearranging for $x_i$:
$$ x_i = \frac{b_i - \sum_{j \ne i} a_{ij} x_j}{a_{ii}}. $$
In an iterative scheme, at iteration $k+1$, you use the old values $x_j^{(k)}$ on the right-hand side:
$$ x_i^{(k+1)} = \frac{b_i - \sum_{j \ne i} a_{ij} x_j^{(k)}}{a_{ii}}. $$
This process defines the Jacobi iteration. The method converges for every initial guess if and only if the spectral radius of the iteration matrix $T_J = -D^{-1}(L+U)$ is less than one, $\rho(T_J) < 1$ (necessary and sufficient). Checking this directly requires eigenvalues, so in practice one uses sufficient conditions, the most common being that $A$ is strictly diagonally dominant (by rows, $|a_{ii}| > \sum_{j\neq i}|a_{ij}|$, or by columns), which implies $\rho(T_J)<1$. Being symmetric positive definite is not sufficient for Jacobi: an SPD matrix can have $\rho(T_J) \geq 1$ (for example, $3\times 3$ with $1$ on the diagonal and $0.9$ off the diagonal has $\rho(T_J)=1.8$), in which case the iteration diverges. (Gauss-Seidel, in contrast, converges for every SPD matrix.)
Why diagonal dominance is sufficient
Let $\mathbf{e}^{(k)}=\mathbf{x}^{(k)}-\mathbf{x}^*$ denote the error. Subtract the exact equation from the update to obtain
$$ \mathbf{e}^{(k+1)}=-D^{-1}(L+U)\mathbf{e}^{(k)}=T_J\mathbf{e}^{(k)}. $$
If $A$ is strictly diagonally dominant by rows, define
$$ q=\max_i\frac{\sum_{j\ne i}|a_{ij}|}{|a_{ii}|}<1. $$
Then $\|T_J\|_\infty=q$ and $\|\mathbf{e}^{(k+1)}\|_\infty\leq q\|\mathbf{e}^{(k)}\|_\infty$. This proves geometric decay without computing eigenvalues. It also gives an error bound from observable steps:
$$ \|\mathbf{x}^{(k+1)}-\mathbf{x}^*\|_\infty\leq\frac{q}{1-q}\|\mathbf{x}^{(k+1)}-\mathbf{x}^{(k)}\|_\infty. $$
For the worked example, $q=1/2$, so the infinity norm of a completed step bounds the remaining error. Without a known contraction bound, a small step can instead indicate slow progress or rounding. A scaled residual such as $\|\mathbf{b}-A\mathbf{x}\|/(\|A\|\|\mathbf{x}\|+\|\mathbf{b}\|)$ supplies an additional check when the denominator is nonzero.
Keep separate old and new vectors during a Jacobi sweep. Overwriting components and reusing them immediately changes the algorithm into Gauss–Seidel iteration.
Algorithm steps
Step 1: Initialization.
Choose an initial guess $\mathbf{x}^{(0)} = (x_1^{(0)}, x_2^{(0)}, \ldots, x_n^{(0)})^\top$. A common choice is the zero vector or a small random vector.
Step 2: Iterative update.
For $k = 0,1,2,\ldots$ (until convergence):
$$ x_i^{(k+1)} = \frac{b_i - \sum_{j=1, j \ne i}^{n} a_{ij} x_j^{(k)}}{a_{ii}}, \quad i = 1, 2, \ldots, n. $$
Step 3: Convergence check.
After computing $\mathbf{x}^{(k+1)}$, check if $\|\mathbf{x}^{(k+1)} - \mathbf{x}^{(k)}\|$ (or $\|A\mathbf{x}^{(k+1)}-\mathbf{b}\|$) is less than a given tolerance $\varepsilon$. If yes, stop; otherwise, continue iterating. The implementation uses the first criterion with the infinity norm, and raises an error if the iteration cap (max_iterations) is reached first.
Example
Given System:
$$ \begin{aligned} 2x - y &= 5, \\ x + 3y &= 7. \end{aligned} $$
In matrix form:
$$ A = \begin{bmatrix} 2 & -1 \\ 1 & 3 \end{bmatrix}, \quad \mathbf{x} = \begin{bmatrix} x \\ y \end{bmatrix}, \quad \mathbf{b} = \begin{bmatrix} 5 \\ 7 \end{bmatrix}. $$
From the equations:
$$ 2x - y = 5 \implies x = \frac{5 + y}{2}, \quad x + 3y = 7 \implies y = \frac{7 - x}{3}. $$
The Jacobi iteration formulas are:
$$ x^{(k+1)} = \frac{5 + y^{(k)}}{2}, \quad y^{(k+1)} = \frac{7 - x^{(k)}}{3}. $$
Step-by-step Calculation:
Initial Guess: Let $x^{(0)} = 0$, $y^{(0)} = 0$.
Iteration 1:
$$ x^{(1)} = \frac{5 + 0}{2} = 2.5, \quad y^{(1)} = \frac{7 - 0}{3} \approx 2.3333. $$
Iteration 2:
Using $x^{(1)} = 2.5$ and $y^{(1)} = 2.3333$:
$$ x^{(2)} = \frac{5 + (2.3333)}{2} = \frac{7.3333}{2} = 3.66665, \quad y^{(2)} = \frac{7 - 2.5}{3} = \frac{4.5}{3} = 1.5. $$
Iteration 3:
Now $x^{(2)} = 3.66665$, $y^{(2)} = 1.5$:
$$ x^{(3)} = \frac{5 + 1.5}{2} = \frac{6.5}{2} = 3.25, \quad y^{(3)} = \frac{7 - 3.66665}{3} = \frac{3.33335}{3} = 1.1111167. $$
Continue iterating until $|x^{(k+1)} - x^{(k)}|$ and $|y^{(k+1)} - y^{(k)}|$ are below a desired tolerance (e.g., $10^{-4}$). Over many iterations, the values will approach the true solution (which, by direct solving, is $x=\frac{22}{7} \approx 3.1429, y= \frac{9}{7} \approx 1.2857$). The Jacobi iterations gradually "home in" on this solution.
Advantages
- The simplicity of implementation is a key advantage of the Jacobi method, as each new approximation depends solely on values from the previous iteration, making the algorithm straightforward to code and understand.
- The Jacobi method supports parallelization effectively because each component $x_i^{(k+1)}$ depends only on values $x_j^{(k)}$ from the previous iteration. This allows computations for all $i$ to be performed simultaneously, using modern parallel computing hardware such as multi-core CPUs or GPUs.
- The method is easy to apply to any system whose diagonal elements are nonzero (a zero diagonal entry makes the update undefined). Nonzero diagonal only makes the iteration defined, not convergent: convergence is guaranteed under strict diagonal dominance (or, more generally, whenever $\rho(D^{-1}(L+U)) < 1$), and techniques such as relaxation can expand its usability.
Limitations
- Convergence is conditional: it requires $\rho(D^{-1}(L+U)) < 1$, which strict diagonal dominance is sufficient (but not necessary) for. Symmetric positive definiteness is not enough. Without such a condition, the method may diverge, oscillate, or converge at an impractically slow rate.
- The Jacobi method suffers from slow convergence compared to more advanced iterative methods like Gauss-Seidel or conjugate gradient methods. Its relative inefficiency often makes it less attractive for practical applications unless used as part of a preconditioning strategy.
- The method exhibits sensitivity to the initial guess. Although a poor initial guess does not affect the correctness of the final solution if convergence occurs, it can significantly increase the number of iterations needed. For a convergent linear iteration there are no competing local optima; apparent stagnation reflects the convergence factor, conditioning, stopping tolerance, or finite arithmetic.