Gauss-Seidel Method
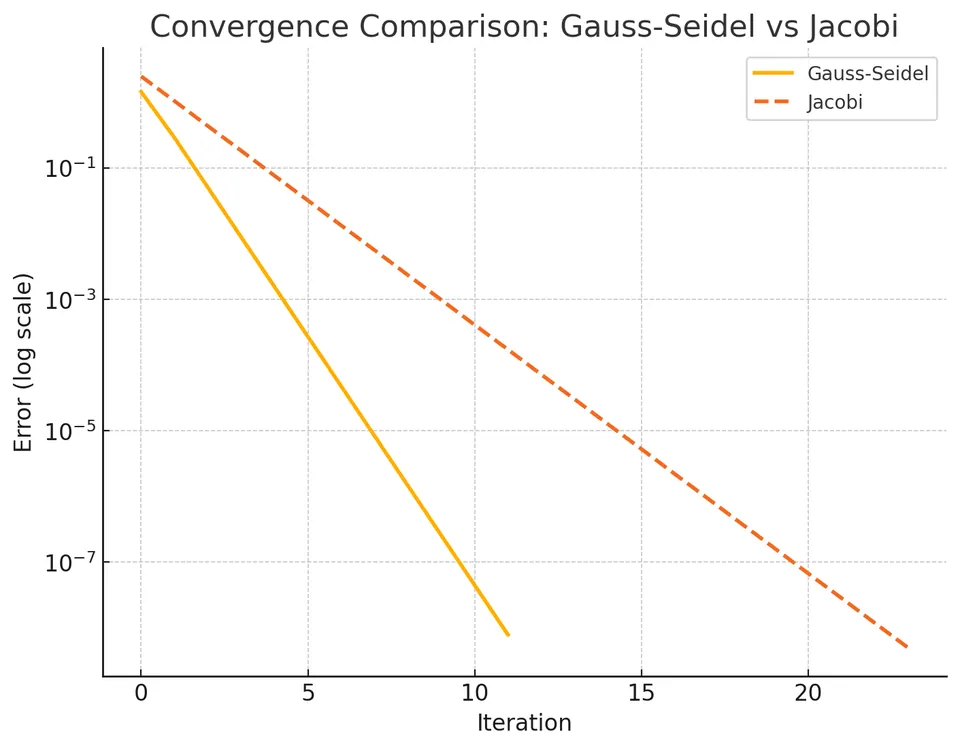
Gauss–Seidel is an iterative method for a linear system $A\mathbf x=\mathbf b$, with $A\in\mathbb R^{n\times n}$, unknown vector $\mathbf x=(x_1,\ldots,x_n)^\top$, and given right-hand side $\mathbf b$. It updates one component at a time during a sweep through the equations. Each new component is used immediately in the remaining updates, while components not yet visited retain their previous values. This distinguishes it from Jacobi iteration, which computes a complete new vector from the old one. The immediate reuse often improves convergence on suitable systems, but it does not provide a universal speed or convergence advantage for every matrix or ordering.
Physically and numerically, the idea behind the Gauss-Seidel method can be interpreted as performing a sequence of "relaxations": starting from some initial guess, the method adjusts one variable at a time to satisfy its current equation, immediately using the most recent updates. The residual is the discrepancy $A\mathbf{x}-\mathbf{b}$; its norm need not decrease after every component update or even after every complete sweep. The algorithm is simple to implement and is widely used for large and sparse systems, such as those arising in discretized partial differential equations, engineering simulations, and large-scale scientific computations.
Mathematical formulation
Consider a system of $n$ linear equations with $n$ unknowns:
$$ A\mathbf{x} = \mathbf{b}, $$ where
$$ A = \begin{bmatrix} a_{11} & a_{12} & \cdots & a_{1n} \\ a_{21} & a_{22} & \cdots & a_{2n} \\ \vdots & \vdots & \ddots & \vdots \\ a_{n1} & a_{n2} & \cdots & a_{nn} \end{bmatrix} $$
$$ \mathbf{x} = \begin{bmatrix} x_1 \\ x_2 \\ \cdots \\ x_n \end{bmatrix} $$
$$ \mathbf{b} = \begin{bmatrix} b_1 \\ b_2 \\ \cdots \\ b_n \end{bmatrix} $$
If $A$ is nonsingular (invertible), there exists a unique solution $\mathbf{x}^*$ such that $A\mathbf{x}^* = \mathbf{b}$.
The Gauss-Seidel method arises from decomposing the matrix $A$ into a lower-triangular part, a strict upper-triangular part, and possibly a diagonal part. One common decomposition is:
$$ A = L + D + U $$
where:
- $D$ is the diagonal part of $A$ (i.e., $D = \text{diag}(a_{11}, a_{22}, \ldots, a_{nn})$),
- $L$ is the strictly lower-triangular part (elements below the diagonal),
- $U$ is the strictly upper-triangular part (elements above the diagonal).
Another way to write the update rule is to solve each equation for the unknown on its diagonal in terms of the other unknowns. The Gauss-Seidel iteration formula is typically given as:
$$ x_i^{(k+1)} = \frac{b_i - \sum_{j=1}^{i-1} a_{ij} x_j^{(k+1)} - \sum_{j=i+1}^{n} a_{ij} x_j^{(k)}}{a_{ii}}, $$ for $i = 1, 2, \ldots, n$.
In other words, when computing $x_i^{(k+1)}$, all the updated values $x_1^{(k+1)}, \ldots, x_{i-1}^{(k+1)}$ are already used, while $x_{i+1}^{(k)}, \ldots, x_n^{(k)}$ remain from the previous iteration.
Derivation
Starting from the linear system $A\mathbf{x} = \mathbf{b}$, write the $i$-th equation explicitly:
$$ a_{ii} x_i + \sum_{\substack{j=1 \\ j \neq i}}^{n} a_{ij} x_j = b_i. $$
Rearranging for $x_i$, we get:
$$ x_i = \frac{b_i - \sum_{j \neq i} a_{ij} x_j}{a_{ii}}. $$
The essence of the Gauss-Seidel method is to "sweep" through the equations in a certain order (usually $i = 1, 2, \ldots, n$), and for each $i$-th equation, replace $x_i$ with the newly computed value. The key difference from the Jacobi method is that as soon as we compute $x_i^{(k+1)}$, we use this updated value in subsequent computations within the same iteration step $k+1$. Thus, for the iteration step $k+1$:
- When computing $x_1^{(k+1)}$, we use only old values $x_2^{(k)}, \ldots, x_n^{(k)}$.
- When computing $x_2^{(k+1)}$, we use the newly updated $x_1^{(k+1)}$ and old values $x_3^{(k)}, \ldots, x_n^{(k)}$.
- This pattern continues until $x_n^{(k+1)}$ is computed using $x_1^{(k+1)}, x_2^{(k+1)}, \ldots, x_{n-1}^{(k+1)}$.
The process is essentially a fixed-point iteration. Under certain conditions, such as $A$ being strictly diagonally dominant or symmetric positive definite, this iteration converges to the true solution $\mathbf{x}^*$.
Matrix iteration and convergence
Using the splitting $A=D+L+U$, collect all the newly updated components on the left:
$$ (D+L)\mathbf{x}^{(k+1)}=\mathbf{b}-U\mathbf{x}^{(k)}. $$
Provided the diagonal entries are nonzero, this lower-triangular system can be solved by one forward sweep. The iteration matrix is $T_{GS}=-(D+L)^{-1}U$; the inverse is notation for analysis, not a matrix to form in the algorithm. Subtracting the exact solution gives
$$ \mathbf{e}^{(k+1)}=T_{GS}\mathbf{e}^{(k)},\qquad \mathbf{e}^{(k)}=T_{GS}^{\,k}\mathbf{e}^{(0)}. $$
Convergence from every starting vector holds exactly when the spectral radius $\rho(T_{GS})$, the largest eigenvalue magnitude, is less than one. Strict diagonal dominance and symmetric positive definiteness are useful sufficient conditions. For an SPD matrix, the same updates can be viewed as exact coordinate minimizations of $\tfrac12\mathbf{x}^\top A\mathbf{x}-\mathbf{b}^\top\mathbf{x}$, which has a unique minimum.
For the two-equation example below,
$$ T_{GS}=\begin{bmatrix}0&1/5\\0&-7/40\end{bmatrix},\qquad \rho(T_{GS})=7/40=0.175. $$
The negative nonzero eigenvalue explains the alternating errors. Variable ordering changes the triangular splitting and can affect convergence. A small change between sweeps should be interpreted together with the residual and the conditioning of $A$.
Algorithm steps
Step-by-step procedure:
Step 1: Initialization. Start with an initial guess $\mathbf{x}^{(0)} = (x_1^{(0)}, x_2^{(0)}, \ldots, x_n^{(0)})^\top$. A common choice is $\mathbf{x}^{(0)} = \mathbf{0}$ or a vector of small random values.
Step 2: Iterative update. For iteration $k = 0, 1, 2, \ldots$ until convergence:
For $i = 1$ to $n$:
$$ x_i^{(k+1)} = \frac{b_i - \sum_{j=1}^{i-1} a_{ij} x_j^{(k+1)} - \sum_{j=i+1}^{n} a_{ij} x_j^{(k)}}{a_{ii}}. $$
Step 3: Convergence check. After completing the update for all $i$, check if the solution has converged. A common convergence criterion is to check the norm of the residual $\|A\mathbf{x}^{(k+1)} - \mathbf{b}\|$ or the difference between successive iterates $\|\mathbf{x}^{(k+1)} - \mathbf{x}^{(k)}\|$. If this measure is less than a prescribed tolerance $\varepsilon$, stop; otherwise, proceed to the next iteration. The implementation uses the difference between successive iterates (2-norm) and raises an error if the iteration cap (max_iterations; the old name max_iter is a deprecated alias) is reached first.
Step 4: Output. Once the loop terminates, $\mathbf{x}^{(k+1)}$ is considered the converged solution.
Example
Given System:
$$ \begin{aligned} 5x - y &= 6, \\ 7x + 8y &= 20. \end{aligned} $$
This can be expressed in matrix form as:
$$ A = \begin{bmatrix} 5 & -1 \\ 7 & 8 \end{bmatrix}, \quad \mathbf{x} = \begin{bmatrix} x \\ y \end{bmatrix}, \quad \mathbf{b} = \begin{bmatrix} 6 \\ 20 \end{bmatrix} $$
We have two equations:
I. $5x - y = 6$
II. $7x + 8y = 20$
Step-by-Step Iteration:
Initialization:
$$ x^{(0)} = 0, y^{(0)} = 0 $$
Iteration 1 ($k=0$ to $k=1$):
Update $x$:
$$ x^{(1)} = \frac{6 - (-1)\cdot y^{(0)}}{5} = \frac{6 - 0}{5} = \frac{6}{5} = 1.2. $$
Update $y$:
Here, we use the newly computed $x^{(1)} = 1.2$:
$$ y^{(1)} = \frac{20 - 7 \cdot (1.2)}{8} = \frac{20 - 8.4}{8} = \frac{11.6}{8} = 1.45. $$
After first iteration:
$$ x^{(1)} = 1.2, \quad y^{(1)} = 1.45. $$
Iteration 2 ($k=1$ to $k=2$):
Using $x^{(1)} = 1.2$ and $y^{(1)} = 1.45$:
Update $x$:
$$ x^{(2)} = \frac{6 - (-1)\cdot(1.45)}{5} = \frac{6 + 1.45}{5} = \frac{7.45}{5} = 1.49. $$
Update $y$:
Using $x^{(2)} = 1.49$:
$$ y^{(2)} = \frac{20 - 7 \cdot (1.49)}{8} = \frac{20 - 10.43}{8} = \frac{9.57}{8} = 1.19625. $$
After second iteration:
$$ x^{(2)} = 1.49, \quad y^{(2)} = 1.19625. $$
Iteration 3 ($k=2$ to $k=3$):
Using $x^{(2)} = 1.49$ and $y^{(2)} = 1.19625$:
$$ x^{(3)} = \frac{6 - (-1)\cdot(1.19625)}{5} = \frac{6 + 1.19625}{5} = \frac{7.19625}{5} = 1.43925. $$
$$ y^{(3)} = \frac{20 - 7 \cdot (1.43925)}{8} = \frac{20 - 10.07475}{8} = \frac{9.92525}{8} = 1.24065625. $$
After third iteration:
$$ x^{(3)} \approx 1.43925, \quad y^{(3)} \approx 1.24066. $$
If we continue iterating until the changes in $x$ and $y$ are negligible (for example, less than $10^{-4}$), the method converges to approximately:
$$ x \approx 1.4468, \quad y \approx 1.2340 $$
(the exact solution is $x = \frac{68}{47}, y = \frac{58}{47}$).
Advantages of the Gauss-Seidel method
- The Gauss-Seidel method often achieves faster convergence than the Jacobi method because it uses the most recent updates of variables during the same iteration, particularly effective for well-conditioned or diagonally dominant systems.
- Memory requirements are minimal since the method only needs storage for the matrix $A$, the vector $\mathbf{b}$, and the current iterate $\mathbf{x}^{(k)}$, making it efficient for large sparse systems.
- The method’s ease of implementation lies in its simple iterative formulas, which avoid the need for complex matrix factorizations and can be adapted for certain parallel computing environments.
Limitations of the Gauss-Seidel method
- Convergence is not assured unless specific conditions are met, such as when $A$ is strictly diagonally dominant or symmetric positive definite, and it can fail or converge very slowly otherwise.
- Updates in the Gauss-Seidel method are sequential in nature, as each variable depends on previously updated variables from the same iteration, which restricts straightforward parallelization.
- For systems that are ill-conditioned or not sufficiently diagonal dominant, the method can experience a significant slowdown in convergence, necessitating the use of alternative techniques or preconditioners for efficiency.